

Connecting a CRM, an ERP, an ecommerce platform, and custom applications raises an apparently simple question: how do we know that two records represent the same entity? The answer cannot default to a name, email address, or visible reference. Those values change, can be duplicated, and often follow different rules in each system.
A poor decision about identifiers causes duplicates, updates applied to the wrong record, orders without an associated customer, and manual reconciliations that become permanent. A sound decision is not about finding a magic universal identifier, but about defining which system recognizes which entity, with which key, for how long, and under which change rules.
This framework helps you choose among internal IDs, business references, external IDs, and mapping tables without exposing unnecessary information or coupling systems in a fragile way.
Why visible fields do not solve identity
A company name can be written in several ways, change after a merger, or be shared by different organizations. A person's name has even more collisions. An email address can change, be reused, belong to a shared account, or be absent from certain workflows. Even a commercial reference may only be unique within a subsidiary, channel, or time period.
These fields remain useful for searching, displaying, and suggesting matches, but they should rarely be the technical key for an integration. The important distinction is:
- Identity: the specific record that a system considers an entity.
- Attributes: data that describes that entity, such as name, email, phone number, or address.
- Business reference: a code with operational meaning, such as an order number or customer code.
Confusing these layers is a frequent source of errors. For example, an address does not necessarily identify a customer: one person can have multiple addresses, and several people can share one. Likewise, an order identifies a transaction, not its buyer on a permanent basis.
Identifier types and what each one is for
Before designing messages or endpoints, classify the available keys. Each type has advantages and limits.
- Internal ID: a key generated and controlled by one system, usually stable and without business meaning. It is the best option for operating within its own domain.
- Business reference: a readable or operational code, such as an order reference. It helps support and reconciliation, but its format may change, it may restart by series, or it may be reused.
- External ID: an identifier that a receiving system stores to remember a record from a sending system. It is useful when there is a clear relationship of origin.
- Composite identifier: a combination of values, for example
source + entity type + id. It is essential when an ID is only unique within one system. - Temporary identifier: a correlation key for a process that has not yet been finalized. It must expire and must not accidentally become permanent identity.
A practical rule is to retain each application's internal ID as its local authority. When data is exchanged, the minimum safe identifier is usually a value with an explicit namespace. For example:
{
  "entity_type": "customer",
  "source_system": "ecommerce",
  "source_id": "C-48291"
}
The value C-48291 alone is not necessarily globally unique. The source context prevents another system from treating a textual match as a shared identity.
Questions to answer before sharing an ID
Do not choose a key simply because it is convenient to implement. First decide on the ownership model and lifecycle. These questions reveal whether an identifier is suitable for use across systems:
- Which system creates the entity, and which is the source of truth for each attribute?
- Is the value unique across the organization, or only within an application, country, channel, or entity type?
- Can it change? If it changes, is the previous value retained and is an event published?
- Can it be reused after deletion, cancellation, or a retention period?
- Does it contain personal data, sensitive commercial information, or easily guessed patterns?
- Can one record merge into another or split into several?
- What should the receiver do when it cannot find a match?
A shared ID must be stable, unique in its context, non-reusable, and sufficiently opaque for its intended use. If a business reference does not meet these conditions, use it as a verifiable attribute rather than an update key.
Technical identity must also be separated from authorization. Knowing an identifier must not allow someone to read or modify an entity. APIs must validate that the caller is allowed to operate on that resource and must avoid using predictable IDs as the only protection mechanism.
When to propagate the source ID and when to use a mapping table
Propagating the source ID is reasonable when an entity originates in a clearly authoritative system and other systems only need to recognize it. For example, ecommerce can create an order and the ERP can store the ecommerce order identifier as an external reference. This pattern reduces ambiguity and makes origin traceable.
However, not every domain has one authority. A customer may enter through sales, ecommerce, support, or historical imports. In such cases, making one system's ID the universal key creates dependency and can turn a future migration into a high-risk project.
A mapping table is preferable when there are multiple master systems, gradual consolidation, record merges, or complex identity rules. It should store at least the entity type, system, local ID, canonical ID if one exists, link status, creation date, and the evidence or rule that justified the relationship.
Avoid a table that merely connects two columns without context. The same value may exist for different types, and a link can be confirmed, provisional, rejected, or replaced after a merge. Treat this mapping as operational data with auditability, not as invisible configuration in code.
Creation, duplicates, and merges: design for uncomfortable cases
When a new record arrives without a shared identifier, the receiver should not assume it is a new entity, nor that an email match is final. It should apply an explicit policy:
- Create a new record and leave it unlinked when there is insufficient evidence.
- Suggest a match when several consistent attributes exceed a business-defined threshold.
- Require human review to link records with financial, contractual, or customer service consequences.
- Record the decision, the applied rule, and the IDs involved.
Automatic deduplication is especially risky when the cost of an incorrect merge is greater than the cost of keeping two pending records. Incorrectly combining two customers can mix invoices, consents, or communications. A detected duplicate, by contrast, can be resolved through a review queue.
Merges require their own semantics. Define a surviving record, retain historical IDs as aliases or redirects, and publish the change so consuming systems can update their links. Do not immediately remove the absorbed ID: asynchronous processes, retries, and historical records may still refer to it.
Changes, deletions, and reactivations without breaking traceability
An ideal technical identifier does not change. If a business reference must change, the event must communicate both the previous and new value and explain the reason. Never interpret silence as deletion: delays, delivery failures, or synchronization filters may exist.
For deletions, use explicit statuses such as active, inactive, cancelled, deleted, or merged, depending on the domain. Physical deletion may be required by privacy requirements, but it must be designed together with traceability: it may be possible to retain a non-identifiable technical marker or evidence that a link must not be recreated.
Do not reuse references that have already been issued, even when the record is inactive. Reuse turns correct historical data into future ambiguity. If a reactivation represents the same entity, retain the ID; if it represents a new entity, assign a new one and document the relationship only if it provides operational value.
API, message, and operational control design
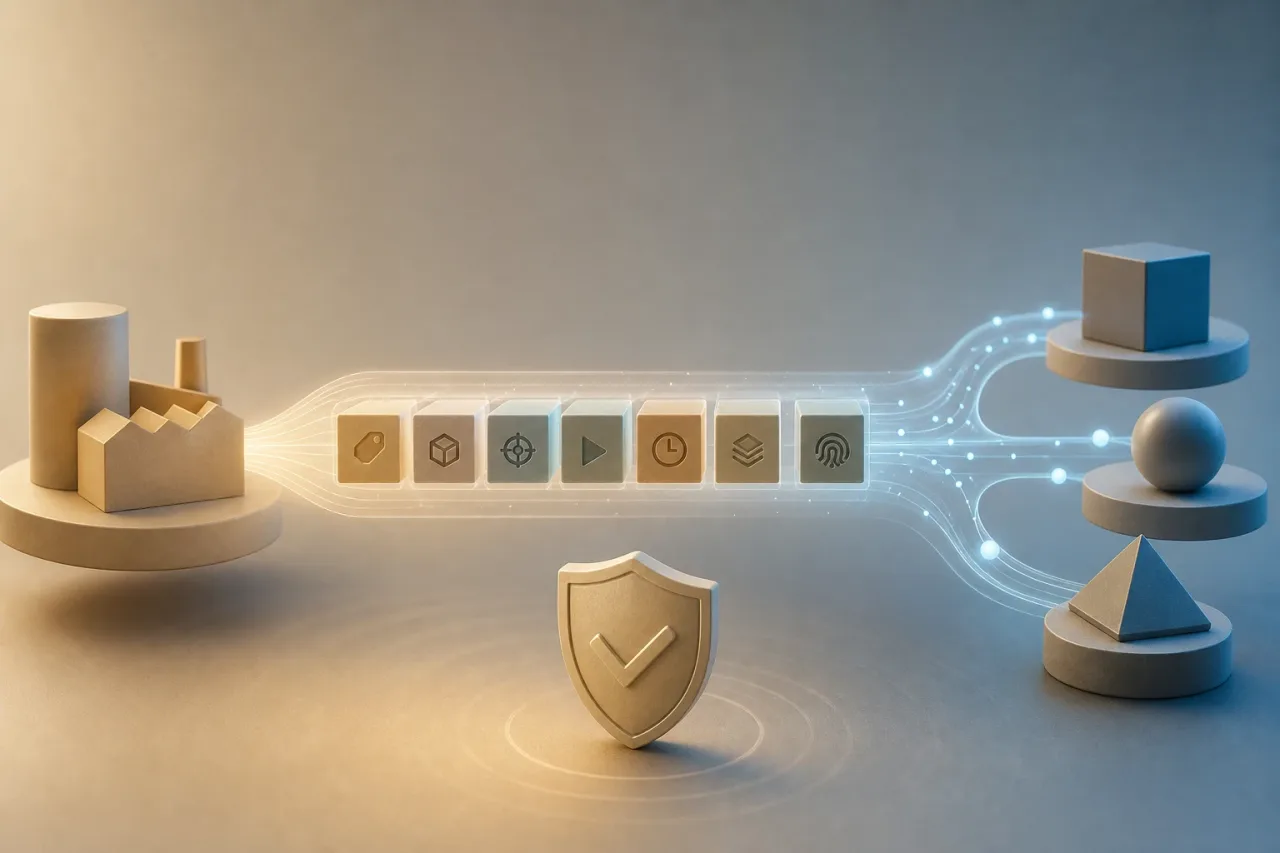
An integration contract should carry sufficient context, but no more data than necessary. Include entity type, source system, source ID, operation, timestamp, version or sequence where applicable, and an event identifier to handle retries. Idempotency prevents the same entity from being created multiple times when delivery is repeated.
For updates, prioritize an operation that clearly indicates the key being used. If searching by business reference is allowed, treat multiple results as a controlled error, not as an invitation to select the first record.
Operational controls should turn identity problems into visible signals:
- alerts for ambiguous matches and messages without a mapping;
- queues for pending links and merge reviews;
- metrics for created duplicates, broken links, and recurring errors by system;
- periodic reconciliations across expected counts, statuses, and links;
- logs containing technical and correlation IDs without exposing unnecessary personal attributes.
Before building, document each entity's authoritative system, local ID, accepted external keys, uniqueness rules, change policy, deletion statuses, and deduplication strategy. This decision reduces coupling today and makes a future migration, audit, or new channel manageable.