

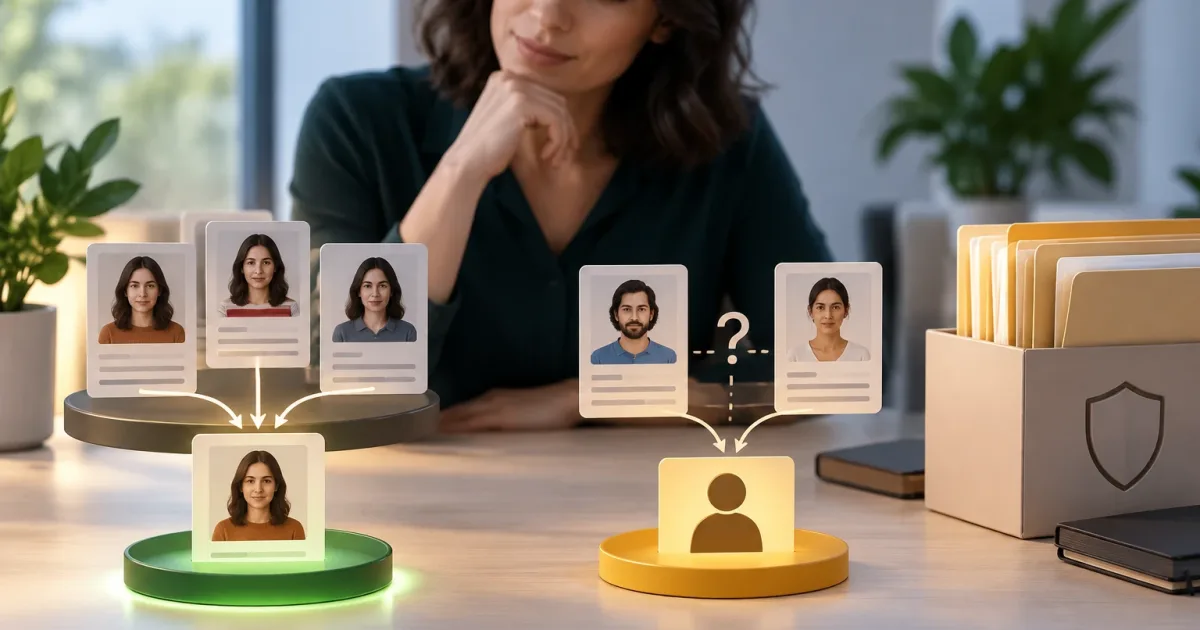
When a person appears with multiple profiles in a CRM, an online store, and other systems, the problem may seem simple: remove the duplicates. But a match does not prove that two records belong to the same customer. An incorrect merge can mix histories, disrupt communications, or attribute a purchase to someone else. The decision requires balancing data quality, operational continuity, and the ability to correct mistakes.
An effective policy is about more than choosing a tool or a matching rule. It defines what it means to be the same person, what evidence is sufficient to act, how conflicts between fields are resolved, and how an operation can be reversed. The goal is to keep connected profiles consistent without deleting information that may still be useful.
Define when two records represent the same customer
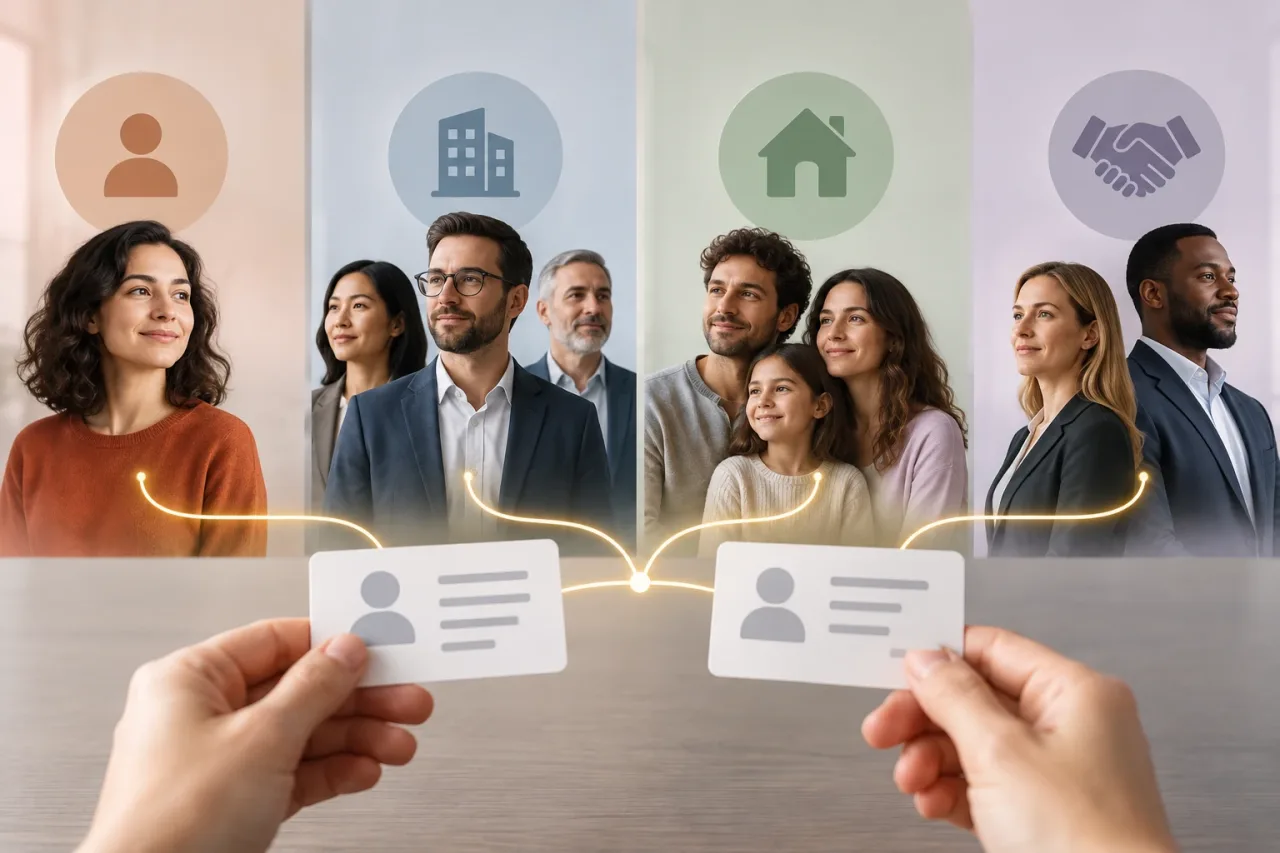
Before comparing data, establish which identity you are trying to resolve. Is it an individual, a business account, a household, or a commercial relationship? In some systems, several people share an email address or phone number; in others, one person uses different email addresses. The policy should account for these situations instead of assuming that an attribute always identifies one individual.
It is also important to distinguish a duplicate from a legitimate relationship. Two profiles may share an address because they live in the same household, or use the same phone number because they share a family line. A person may have both a business account and a personal account. If the business needs to represent these relationships separately, merging them would erase valid distinctions.
Document the purpose of identity resolution and the relevant exceptions. For example, decide whether business accounts are consolidated by organization or by contact, and how test profiles, shared accounts, and incomplete records are handled. This definition should support downstream use: customer service, orders, billing, and communication preferences may each require a different level of detail.
Choose attributes and combine signals
The quality of a match depends on both the attributes selected and how reliable they are. A stable internal identifier can be a strong signal if it is generated and retained correctly. Normalized email addresses, phone numbers, and names provide information, but they can change, be shared, or be entered in different ways. An address can also help with comparison, although it usually cannot identify a person on its own.
Separate exact matches from approximate ones. An exact match on a validated identifier may justify more confidence than a spelling similarity between names. Approximate matching can help with typos, abbreviations, and formatting variations, but it also produces false positives: two people may have the same name or common surname.
Before comparing, normalize formats conservatively. You can standardize capitalization and spaces or compare phone numbers in a consistent format. Do not remove differences that matter to the system or assume that every character can be discarded without consequences. Record which transformations were applied so that results can be explained and reviewed.
Evaluate signals together and treat missing values as missing. If two records have no phone number, that is not a match; if they share one, it may be a weak signal or relevant evidence depending on the context. A clear rule is usually easier to maintain than an opaque set of exceptions. If a scoring model is used, the team should be able to understand which factors influence each decision.
Design three paths: merge, review, or keep separate
A practical policy defines confidence levels and an action for each one. The specific thresholds depend on the data and the cost of getting a decision wrong; there is no universal threshold that can be recommended without evaluating the case. What matters is reserving automated decisions for sufficiently strong matches and providing a clear path for ambiguous cases.
- High confidence: Merge automatically when several reliable signals agree and there is no significant contradiction.
- Medium confidence: Send for human review when signals are compatible but insufficient for a safe decision.
- Low confidence: Keep the records separate and, if appropriate, reassess when new information becomes available.
Human reviewers need context, not just two rows of data. Show the matching and differing fields, their sources, dates, and source systems, along with the effect of accepting the merge. Allow reviewers to reject the proposal and record their reason. If there are many cases, prioritize those with a meaningful operational impact rather than presenting an undifferentiated queue.
Consider the asymmetric cost of errors. An incorrect merge can expose information to the wrong profile or affect a sensitive process; leaving two duplicate profiles can lead to repeated communications or a fragmented view. Depending on the process, one of these errors will be more costly. Thresholds and automation should reflect that difference.
Resolve conflicts without losing provenance
Identifying two records as belonging to the same person does not answer which value should be retained in each field. One system may have the current email address and another the current phone number; one record may contain a legal name and another a preferred name. Applying a general rule, such as always keeping the newest or most complete profile, can overwrite valid data.
Set precedence by field and in context. One system may be the preferred source for billing information, while customers may update their contact preferences through another channel. Consider the date, source, and verification method for a value, not just when it was synchronized. If there is no reliable source, preserve the conflict for resolution instead of inventing a winner.
Keep provenance: the source system, update date, and, where possible, the event that introduced the data. Traceability makes it possible to explain why a value was selected, detect faulty synchronizations, and recover information that should not have been discarded. Fields with legal, commercial, or privacy implications require particular care and rules suited to their use.
Make merges reversible and measurable
Avoid treating a merge as permanent deletion of a record. Maintain a master identifier and references to the original identifiers so that CRM, ecommerce, and other systems can recognize the association. Preserve the history needed to reconstruct which profiles were joined, when, under which rule, and using what data. The specific solution will depend on the architecture, but reversibility should be part of the design, not an improvised repair.
Establish a separation procedure as well. If someone reports that their data has been mixed with another person’s, the team should be able to locate the operation, restore the records, and correct references across connected systems. Decide who can request or approve a separation, how it propagates to connected systems, and how to prevent the same rule from immediately merging the profiles again.
Measure outcomes by rule type and source system. Track how many proposals are merged, how many are rejected during review, how many are separated later, and which field conflicts arise. A high merge rate does not prove quality. Subsequent separations and manual corrections are useful signs of false positives; duplicates that continue to appear may indicate insufficient rules or problems in data capture processes.
Implement the policy in stages
Start with a representative sample and evaluate the rules without changing production records. Review obvious cases, ambiguous cases, and counterexamples: people with identical names, shared email addresses, old data, and incomplete profiles. Refine the criteria with business, operations, and technology stakeholders, because each team understands different consequences of a wrong decision.
- Define which entity is being identified and which cases must remain separate.
- Inventory the systems, available attributes, and the quality and provenance of their data.
- Test exact and approximate rules on a sample reviewed by people.
- Assign clear owners to the merge, review, and separation paths.
- First enable proposal or review mode and record the results.
- Automate only validated matches, and monitor errors and changes.
Review the policy when systems, registration processes, or customer types change. A rule that worked with clean data can deteriorate after a migration or a new integration. The right decision is not to merge the greatest number of profiles, but to consolidate those with sufficient evidence while preserving the ability to explain and correct every merge.