

Choosing where to validate data is more than a technical decision: it affects the user experience, business integrity, and the cost of operating an application. Showing an error as early as possible helps people complete a form, but it does not guarantee that an operation is valid. Moving every check to the server can protect data without preventing unnecessary delays and frustration.
The strongest approach is to assign each rule to the layer that can enforce it with the right information and authority. The interface guides users; the server protects business rules; asynchronous processes handle slow checks or those that depend on external services. In many workflows, all three layers work together.
Why one layer is rarely enough
Validation performed only in the interface can be fast and clear, but it may be bypassed by calling an API directly, manipulating a request, or using a different client. For that reason, it must never be the only safeguard for a rule that protects data or business decisions.
At the other extreme, validating everything after submission makes people wait to discover simple errors, such as leaving a required field blank or entering an incorrectly formatted email address. Some checks also take longer than a typical request or depend on systems that may be unavailable.
The useful question is not “which layer validates the data?” but “which layer offers the best combination of speed, authority, and context for each rule?” For example, a length rule can be flagged in the browser and checked again on the server. The interface improves the interaction; the server still decides whether to accept or reject the data.
Interface: immediate feedback, not final authority
Interface validation is useful for catching problems early when they can be explained without consulting external sources: empty fields, character limits, basic formats, or simple combinations. It reduces failed attempts and helps people understand what is missing before they submit a form.
For validation to be useful, the message should appear next to the field or in an accessible summary, explain the problem, and suggest how to fix it. Avoid errors that appear too soon and interrupt someone who is still typing. A reasonable practice is to check when a person leaves a field or submits the form, then update the message when the value changes.
The interface can also anticipate known constraints, such as the expected date format. However, it should not treat an action as valid just because the form accepts it. The browser may be out of date, the client may be modified, and the request may arrive through another route.
- Use it for quick feedback and simple rules that improve data entry.
- Do not rely on it for authorization, permissions, final prices, or record integrity.
- State constraints clearly and avoid messages that expose sensitive information.
Server: authority over business rules
The server must check again any condition whose violation could alter data, grant improper access, or lead to an incorrect decision. This includes validating that the user is allowed to perform the operation, that values belong to the authorized context, and that state transitions are permitted.
The check should happen where the data is accepted or changed, not just on a particular screen. If several applications consume the same API, the server provides a shared policy. It must also handle concurrency: two requests may compete for a resource or try to change the same record.
Server-side validation does not remove the need for understandable messages. When it is safe to do so, the response should distinguish between malformed data, a violated business rule, and a lack of authorization. Avoid returning internal details, queries, traces, or information that could help exploit the system. OWASP guidance on input validation is a useful reference for treating received data as untrusted.
Practical rule: if a result protects a decision or the integrity of the system, the server has the final say, even if the interface applies an equivalent check to reduce friction.
Asynchronous processes: external dependencies and delayed results
Some rules cannot be resolved with a local check or a single quick request. Verifying an address with an external service, analyzing a file, or completing a review that takes time may leave the initial submission in a pending state.
In these cases, separate acceptance of the request from the final result. The system can confirm that it received the operation and report that it is pending without claiming that it is already valid. When the check is complete, it should update the status and communicate the result through a mechanism appropriate to the product, such as a status page or notification.
Design the failure path, too: what happens if the external service does not respond, returns an inconclusive result, or recovers after an outage? Define time limits, reasonable retries, and a way to review or recover. A timeout does not prove that the data is invalid; it may mean that the check could not be completed.
If the result may arrive after the user has left the screen, the status should remain available for them to check. Prevent a late response from overwriting a more recent change by associating the result with the operation or version that was checked.
Deciding where each rule belongs
Assess each validation rule by asking four questions: How costly is a mistake? What information does the check need? How long does it take to become available? And who has the authority to decide? These questions help separate rules that are often mixed together in a single form.
- User experience: if a check is simple and the error can be fixed immediately, show it in the interface.
- Security and integrity: if it affects permissions, persisted data, or a financial decision, enforce it on the server.
- Dependencies and latency: if it requires remote services or lengthy analysis, represent a pending state and handle the result later.
- Cost of error: the greater the impact of accepting an incorrect value, the more controls and traceability are needed.
A rule may need more than one layer, but every layer does not have to resolve it in exactly the same detail. An interface can check that a field is not empty; the server can also apply context and permission constraints. Redundancy is useful when each check has a clear purpose.
Consistency without divergent duplication
The risk of repeating a rule is that it changes in one layer but not another. The interface might accept a value the server rejects, or block one that is already valid. To reduce these inconsistencies, define business rules with an identifiable source of truth and maintain clear contracts between the client and API.
Where the architecture allows it, schemas or validation components can be shared between client and server. This does not make the client authoritative: the server must run the check at its own trust boundary. If sharing an implementation is not feasible, document the criteria, edge cases, and expected responses, and add tests for both sides.
Pay particular attention to rules that change over time or depend on the user, region, account status, or resource availability. Do not hard-code decisions in the interface as constants when the server can update them. If informational constraints are sent to the client, treat them as guidance that may have become outdated.
Errors that explain what to do next
An actionable error identifies the affected data, explains the reason without jargon, and suggests a next step. If the issue can be fixed before submission, associate the message with the field. If the operation is already underway, explain its overall status and how to check or repeat the action. To avoid duplicates on retry, the design must account for what happens if the first request completed but its response never reached the client.
Do not use a field-level message for a condition that depends on the overall process state. For example, if a resource is no longer available, explain what changed and offer alternatives rather than simply marking the field format as incorrect. If revealing the exact reason is unsafe, provide a neutral explanation and a way to continue.
Pre-launch checklist
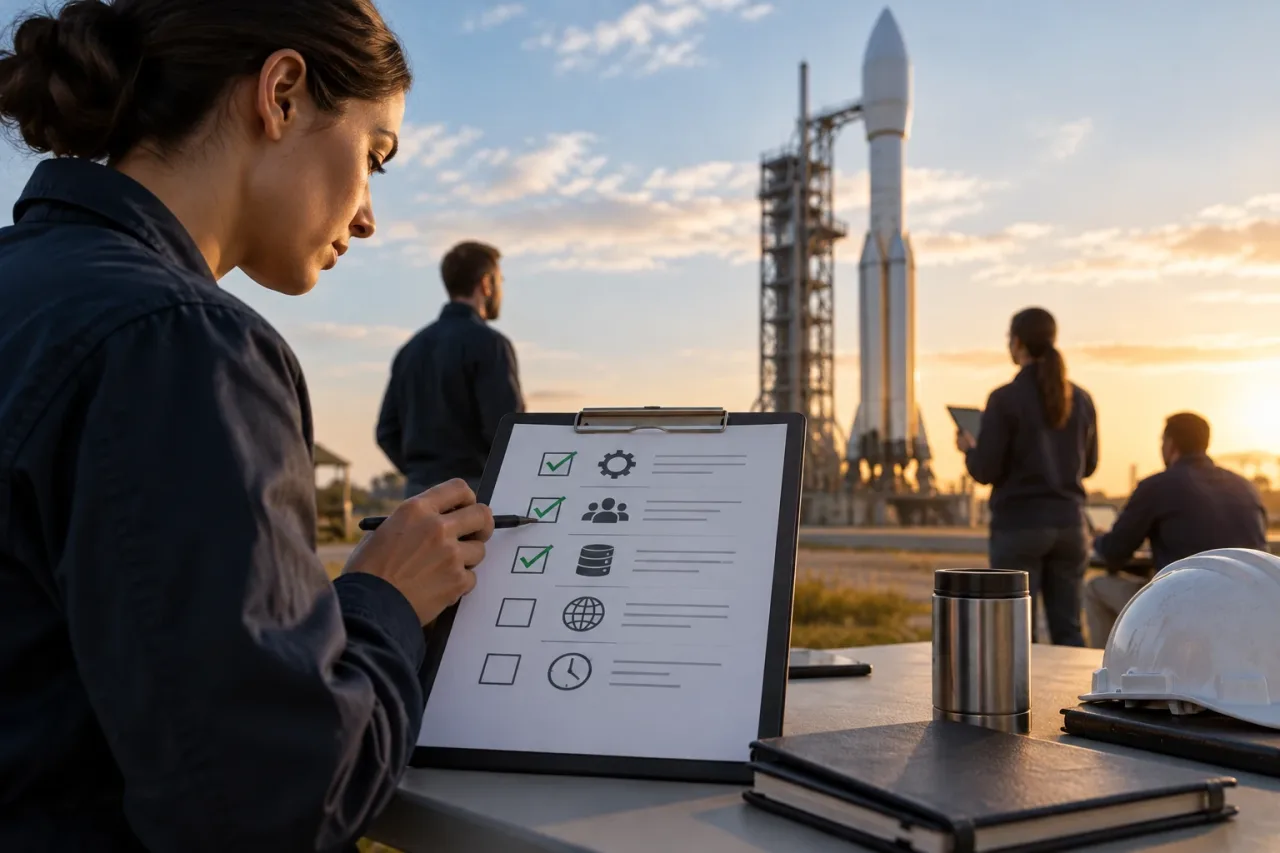
- List the rules and identify which concern format, business logic, authorization, or external dependencies.
- Confirm that every critical rule is checked on the server before a change is accepted.
- Review whether interface messages are timely, accessible, and actionable.
- Define pending states, temporary failures, retries, and late responses.
- Test direct API requests, boundary values, permissions, and concurrent changes.
- Check that errors do not expose internal data and that they indicate the next step.
- Assign owners to update shared rules when the product changes.
The best design does not validate everything everywhere or always wait for the server. Combine early feedback with clear authority and explicit handling of delayed checks. This makes the application easier to understand for users and more resilient to invalid data, changing contexts, and dependency failures.