

Automating a process does not require automating every decision within it. The same operation may include a repeatable check, a data-based recommendation, and an exception that requires an understanding of context the system does not have. Treating the entire workflow as if it required the same level of autonomy creates two opposite problems: human controls that only add delay and automations that make decisions with consequences that no one can explain or correct in time.
The useful question is not whether a person or an automation performs an entire process better. It is which specific decision is delegated, under what conditions, with what evidence, and how control is regained when something falls outside what was expected. This approach makes it possible to reduce manual work without transferring business, customer service, compliance, or operational risks to an opaque rule.
Separate the task from the decision
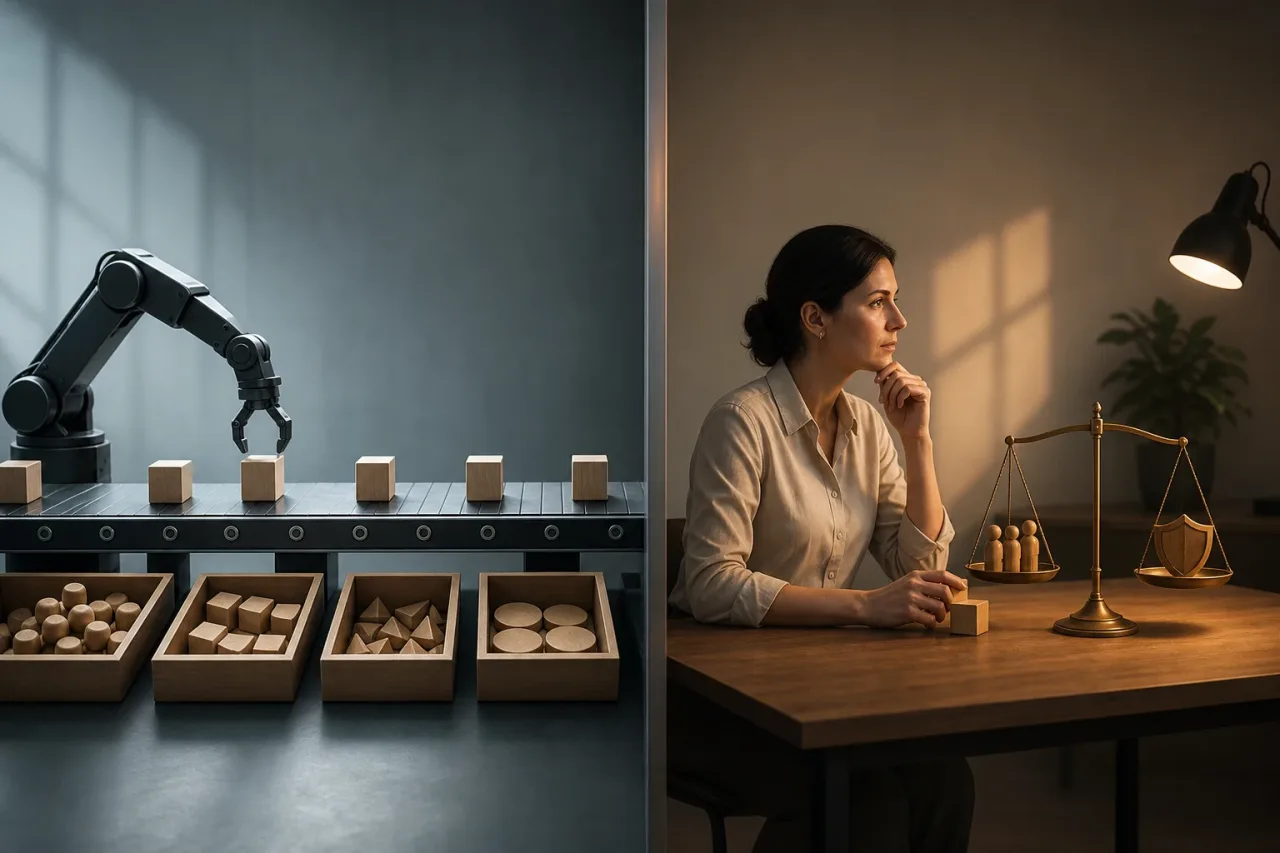
A task is a sequence of actions: classifying a request, updating an order, routing a case, or preparing a payment. A decision determines the consequence of that task: accepting, rejecting, prioritizing, assigning, changing, or escalating. Automation is often appropriate for executing defined steps; the required level of caution should increase when it makes decisions about a customer's rights, revenue, access to information, contractual commitments, or exposure to fraud.
Before choosing technology, break the process down into observable decisions. For example, order management is not a single decision to “approve an order.” It may involve address validation, inventory checks, detection of incomplete information, release for fulfillment, and cancellation based on a risk signal. Each has different impact, available data, and reversal options.
- Input: which data, signals, and documents are used.
- Rule or criterion: which condition changes the outcome.
- Output: which action, communication, or record is produced.
- Consequence: who is affected and what an error costs.
- Recovery: how an incorrect action is corrected and who can do it.
This separation prevents a common misconception: assuming that because a system can classify or score a case, it should also execute the resulting outcome. A model may detect that a request appears urgent; business policy may require a person to confirm a priority that displaces commitments to other customers.
The four modes of intervention
There is no binary split between manual work and autonomous automation. Designing four intermediate modes helps select proportionate controls and makes clear who is accountable for the outcome.
Inform without recommending
The system gathers information, detects a condition, or presents a summary, but does not suggest a decision. This is suitable when data quality is still being explored, when the criterion is not yet stable, or when context is decisive. It is also a safe way to observe patterns before introducing action rules.
Recommend with human decision-making
The automation proposes a classification, priority, or next action and shows its evidence. The person accepts, changes, or rejects it. This is appropriate for cases with material impact or frequent ambiguity: commercial exceptions, sensitive customer requests, or assessments where the data does not capture the full situation.
Execute with mandatory approval
The system prepares the action and requests authorization before applying it. Use this mode when execution is costly to reverse but preparation is repeatable. For example, it can prepare changes to administrative records and leave final publication to an accountable role. Approval must serve a real purpose: access to relevant data, authority to disagree, and reasonable time for review.
Execute automatically with subsequent review
The automation acts within explicit limits, records the decision, and allows later auditing or sampling. This is the most efficient mode for frequent, well-defined, reversible decisions. It does not mean the absence of oversight: it requires alerts, accountable owners, and a correction path. If there is no practical way to detect and repair errors, autonomy is premature.
The five criteria that determine the level of autonomy
Assign an intervention mode to each decision, not to the entire process, by considering these criteria together.
- Impact. The greater the consequence for a customer, an obligation, reputation, or revenue, the greater the oversight should be. An error that changes an internal label does not warrant the same control as one that cancels a commercial relationship.
- Reversibility. Ask how much it costs to undo the action, how much time is available, and whether the affected person may experience a consequence before the correction. The technical ability to reverse a record is not enough if an incorrect communication has already been sent.
- Data uncertainty. Assess coverage, freshness, consistency, and missing cases. Incomplete data, recent changes in behavior, or conflicting signals are reasons to escalate, not to force a decision.
- Frequency and volume. Highly repetitive decisions justify investment in rules, controls, and monitoring. However, volume does not make an ambiguous criterion safe; it only amplifies its errors.
- Need for context. Keep a person involved when the outcome depends on intent, a prior relationship, nuances of language, exceptional circumstances, or a negotiation that is not represented in the systems.
Rule of thumb: a decision can be executed automatically if its impact is limited, its data is reliable, its outcome is reversible, and there is a clear exception path. If two or more conditions fail, begin with recommendation or approval.
Build a decision matrix and escalation rules
The matrix does not need a seemingly scientific score to be useful. It is enough to document a consistent, reviewable criterion. For each decision, define the initial mode, operating limits, and the owner of exceptions. The aim is for someone in operations, product, or technology to understand why the system acted and when it should be stopped.
- Human control: high impact, a difficult-to-reverse outcome, weak evidence, or relevant context. The system may inform or recommend.
- Partial automation: clear rules in most cases, but uncertain ranges, incomplete documentation, or conflicting signals. The automation executes only cases that meet strict conditions.
- Bounded autonomous execution: a frequent decision, low individual consequence, validated data, and a tested reversal mechanism. Samples and exception metrics are reviewed.
Thresholds should express understandable business conditions, not only technical values. A rule such as if required data is missing, do not execute and create a review case is more governable than logic that silently attempts to infer an outcome. Also define what happens when there is a failure: stop the automation, send the case to a queue, apply a safe alternative, or notify an owner.
Avoid exception paths without an owner. Each escalation should identify a team or role, an expected timeframe, the information it will receive, and the possible action. Otherwise, complex cases accumulate and the team ends up ignoring alerts or approving in bulk.
Apply the framework in common situations
In customer service, an automation can identify the topic of a message and suggest a response based on approved information. It can respond autonomously to simple, repeated questions if it does not change conditions or disclose sensitive information. It should escalate when it detects a complaint, an out-of-policy request, a possible privacy incident, or language indicating significant dissatisfaction.
In commercial operations, it can assign contacts based on territory or availability when the necessary fields are complete and the rules are stable. By contrast, changing terms offered to a customer should require approval if it depends on negotiation, history, or exceptions to the current policy.
In internal administration, an automation can validate that a request includes required fields, remind someone about pending documentation, or record an action that has already been authorized. If it must grant access to systems, change critical data, or approve a disbursement, it is advisable to separate automated verification from human authorization unless an expressly defined low-risk policy exists.
Record evidence, measure outcomes, and correct the design
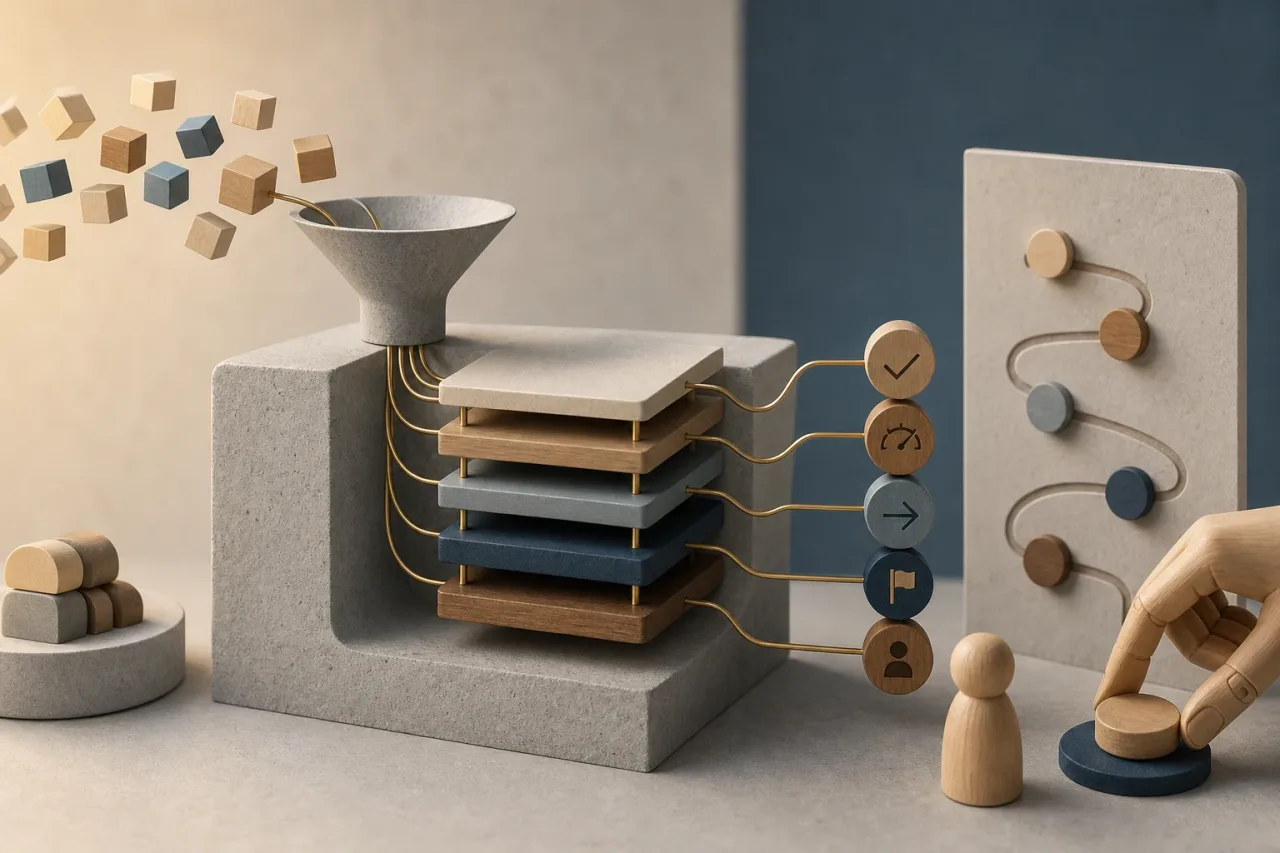
An automated decision should leave a record that makes it possible to answer what happened without reconstructing the case from memory. Record the version of the rule or model applied, relevant input data, the result, the confidence level or threshold condition when applicable, the action taken, exceptions, and any human intervention. This is not about retaining all data indiscriminately, but about keeping evidence that is proportionate and useful for operating, correcting, and being accountable.
The NIST AI Risk Management Framework is useful as a reference for integrating risk assessment and monitoring, especially when AI systems are involved. Data management is also decisive: if definitions, owners, and quality controls are ambiguous, an automation will reproduce that ambiguity at scale.
Review the level of autonomy when these signals appear:
- corrections or reopened cases from automatically executed decisions increase;
- the percentage of exceptions grows or their types change;
- people accept recommendations without reviewing them, or reject them frequently;
- policies, data sources, integrations, or market conditions change;
- affected people report outcomes that are difficult to understand or correct.
Before production, confirm that every decision has a purpose, an owner, defined data, visible thresholds, an exception path, an evidence record, and a tested reversal mechanism. The best automation does not eliminate human judgment: it reserves it for the cases where it makes a material difference.