

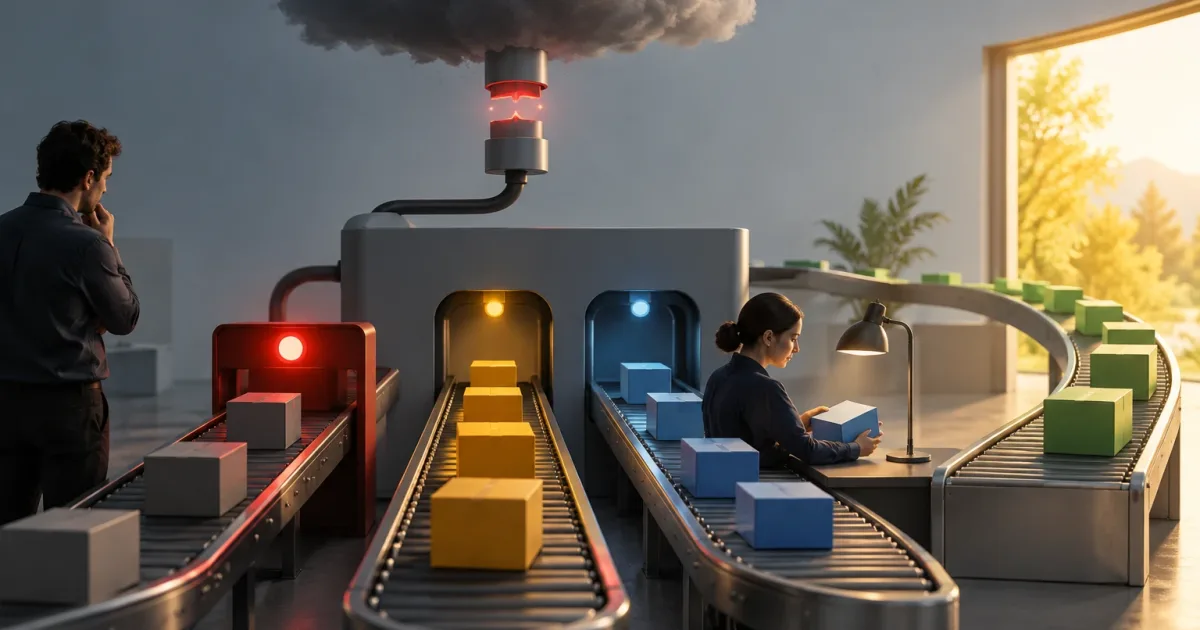
An automation that depends on an API or another external service can fail even when its own process is working correctly. The important question is not only how to detect an incident, but what should happen while the dependency is unavailable. A uniform decision—to stop everything or carry on at any cost—is often unsuitable. The impact depends on the affected function, the data required, and the consequences of acting late or with incomplete information.
A contingency policy translates these factors into operational decisions. It determines when to block, when to continue with limitations, and when to send a case to a person; it also establishes how to process pending work once service resumes. This reduces improvisation and prevents a technical interruption from accidentally becoming a business decision.
Classify the impact before choosing a response
Start by describing what the dependency contributes to each process. The same provider may be essential for one operation and dispensable for another. For example, if a service enriches a record to support later analysis, it may be acceptable to save the record without that data. If the service verifies a condition required to authorize an operation, proceeding without a response may be unsafe or violate an internal rule.
For each use, assess what happens if the task stops, is delayed, or is completed with incomplete data. Consider both the potential harm and whether it can be corrected later. A useful classification distinguishes between:
- Blocking: Proceeding without the external response could cause an unauthorized action, a loss that is difficult to reverse, or a high-impact incorrect result.
- Deferrable: The task can wait without causing significant harm, provided someone can identify and handle it within an acceptable operational timeframe.
- Degradable: Some value can still be delivered without the service, with clear limitations and without presenting an incomplete result as complete.
- Reviewable: The system lacks enough information to decide safely, so it must retain the case and request human intervention.
Do not classify by component alone. Record the process, operation type, affected data, and consequences of each alternative. If the result has contractual, financial, privacy, or security implications, involve the responsible teams in the decision.
Choose whether to block, degrade, or escalate
Blocking is appropriate when the external response is a necessary condition and there is no authorized alternative. The block must be explicit: report that the operation was not completed, preserve the context so it can be resumed, and avoid ambiguous states that look successful. Define what the user can do in the meantime, such as save a draft or try the operation again later.
Continuing in degraded mode makes sense when a secondary function can be omitted without compromising the essential result. Limit what the system allows, identify missing data, and communicate the limitation to the user or team receiving the result. Do not turn a missing response into a seemingly valid default value if that could mislead someone. It is also useful to distinguish an unknown value from one confirmed as negative.
Escalating to a person is an option when judgment is needed but the task can still be resolved. Escalation requires a visible queue, enough information to make a decision, and a clear indication of what the person should review. Without these elements, “manual mode” merely moves the failure into a disorganized inbox. Also define who is responsible for handling cases and what happens if they are not reviewed in time.
These responses can vary by operation. There is no need to assign a single mode to the entire integration: an informational lookup might degrade, while an action that changes a sensitive record is blocked. Document exceptions, and do not let behavior depend on assumptions hidden in the code.
Set safe limits for the manual alternative
A manual procedure should be a controlled exception, not an unsupervised parallel route. Before enabling it, define which roles may intervene, which actions are permitted, and for how long. Authorization should match the risk: not everyone who reviews a case needs permission to approve or modify it.
Also specify what evidence must be recorded. At a minimum, retain the affected operation, the information available at the time, the decision made, who made it, and when. If a person enters a provisional value, make its origin clear and note whether it needs later confirmation. Keep facts received from the service separate from human decisions; that distinction makes auditing and correction easier.
The alternative needs a time limit or a closing condition. For example, it might stop being available when the queue reaches a capacity set by operations, an authorization expires, or the dependency becomes available again. Do not invent a universal threshold: choose one based on volume, review costs, and the risk of accumulating unresolved work. If capacity is insufficient, blocking new operations may be safer than creating invisible operational debt.
Define when to resume and how to reconcile pending work
An API responding again does not, by itself, prove that it is safe to process everything that has accumulated. Define recovery signals appropriate to both the dependency and the process: sustained availability for a period set by the team, valid responses for the operations required, and no discrepancies that require resumption to stop. The criteria must be verifiable, not based on an impression.
Before resuming, decide what to do with each pending state. Some cases can be reprocessed automatically; others require checking whether the operation was partially completed or resolved manually. Avoid duplicating actions: identify operations in a way that lets the system recognize which have already been performed and which remain open. If you cannot confirm the final state, send the case for review instead of assuming that repeating it is harmless.
Reconciliation should compare what was expected with what happened: tasks received, manual decisions, completed operations, and errors that remain open. Define who validates closure and how discrepant data will be corrected. This means recovery does not end when the provider comes back; it ends when the internal process has returned to a consistent state.
Test scenarios and review the policy
Test unavailability in a controlled environment and walk through the process from the perspectives of both users and operations. Include delayed responses, incomplete data, intermittent recovery, and an outage during an action in progress. The goal is not to test a generic list of failures, but to confirm that each documented decision is carried out and that the people responsible understand what they need to do.
Watch for signs of a design problem: cases marked as complete without a valid response, manual queues growing without an owner, users repeating an operation because they do not know its status, or pending tasks that are not reconciled after recovery. Also review the effects on response times, data quality, and additional work. If an alternative creates more risk or cost than waiting, change the policy.
Update the decision when the process, provider, permissions, or impact of an operation changes. A contingency that is valid for an informational function may no longer be suitable if it begins triggering an action with greater consequences. The review should involve product, technology, and operations, as well as other relevant teams when the risk requires it.
Dependency checklist
- Which processes and decisions depend on this external service?
- What are the consequences of stopping, delaying, or completing each operation without all the data?
- What conditions determine whether to block, degrade, or escalate to a person?
- What permissions, time limits, and records does the manual route require?
- Who handles pending cases, and when is workload escalated?
- What verifiable signals authorize processing to resume?
- How are duplicates, partial states, and manual decisions identified?
- What tests and reviews keep the policy current?
Answering these questions turns an external dependency into an explicit product and operations decision. The right policy does not eliminate outages: it limits their effects, keeps exceptions visible, and provides a verifiable route back to normal work.