

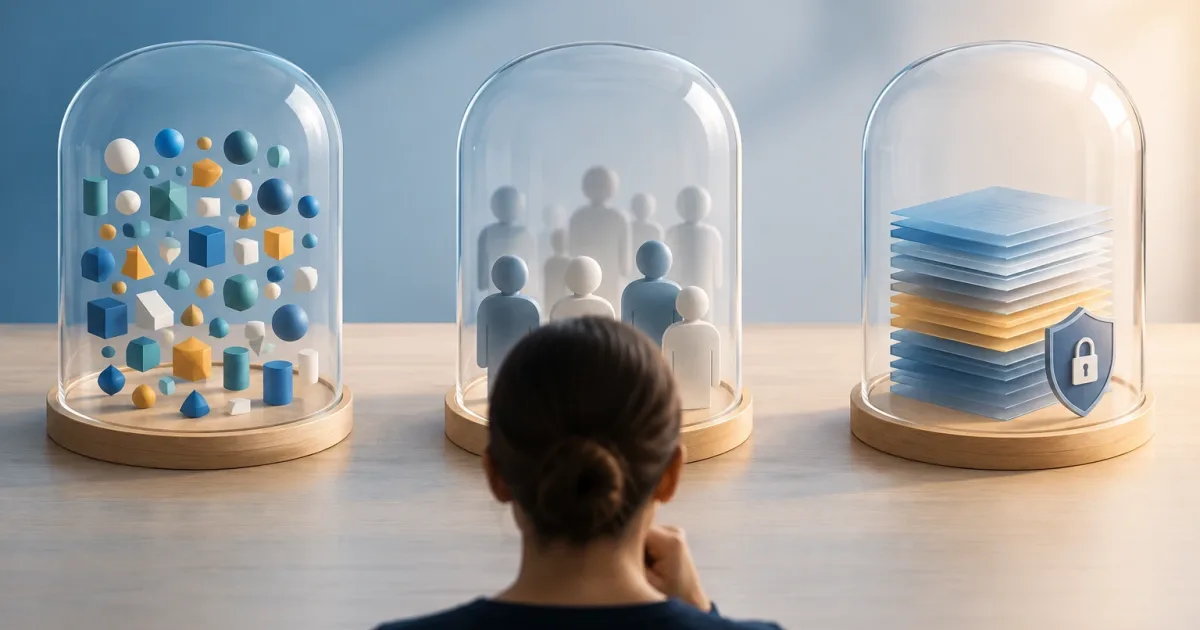
Test data affects both software quality and the exposure of sensitive information. A dataset that is too simple can hide defects; an uncontrolled production copy can disclose personal or business information. The decision is not simply whether to use real or fictional data. It means balancing realism, sensitivity, maintenance effort, and the purpose of each environment.
This guide compares three approaches—synthetic data, anonymized data, and controlled copies—and sets out practical criteria for development, testing, and demonstrations. The right choice can vary between teams and even between tests within the same product.
Why data shapes quality and risk
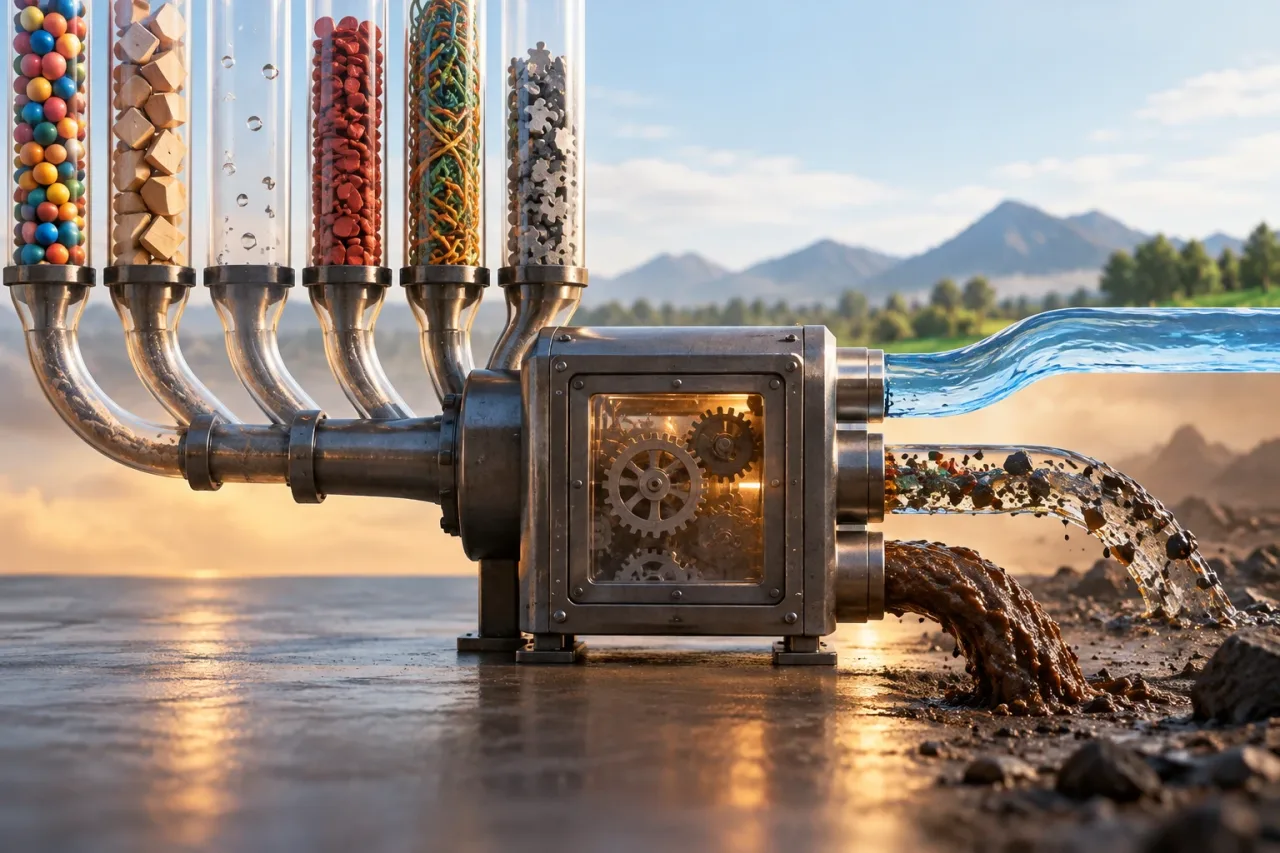
An application behaves according to the data it processes. Volumes, combinations, missing values, duplicates, and relationships between records can trigger paths that basic examples never reach. If tests cover only the ideal case, they can miss failures in validation, calculations, permissions, integrations, or migrations.
At the same time, non-production environments often have more users with access, debugging tools, and less stringent lifecycles than production. Including identifiable information for convenience increases the impact of an exposed account, an accidental export, or an environment that has been left behind. The aim is to preserve the characteristics needed for testing, not to copy more information than necessary.
Before choosing a method, define what you want to validate: a business rule, a migration, performance, a user experience, or a demonstration. Without a clear purpose, “realistic data” is an imprecise requirement and can lead to collecting details that add no value.
Three approaches with different levels of fidelity
Synthetic data
Synthetic data is generated from scratch using rules, templates, or internal tools. It can include fictional names, dates, statuses, and consistent relationships, as well as deliberately designed edge cases. Because it does not originate from real records, it avoids directly transferring production data. However, it is not automatically safe if it contains real values, secrets, or copied examples.
Synthetic data is suitable for development, automated testing, training, and demonstrations when the structure and expected behavior can be described. The main cost is building and maintaining generators that reflect relevant business rules, distributions, and combinations. A dataset that is too uniform will not uncover problems caused by irregular historical data.
Anonymized data
Anonymized data is produced by transforming source data so that individuals cannot be identified. The result may preserve useful patterns for certain tests, but the risk depends on the context, the fields retained, and whether the information can be combined with other sources. Replacing names or email addresses may not be enough: dates, locations, indirect identifiers, and unusual relationships can also reveal identities.
This approach requires reviewing the result, not simply running a transformation. If a test needs only aggregated trends, reducing the level of detail may be appropriate. If it needs relationships between records, the transformation should preserve that consistency without retaining unnecessary identifiers. Anonymization should not be treated as an automatic guarantee that any later use is harmless.
Controlled production copies
A controlled copy retains a selected portion of real data or a transformed, restricted version of it. It can be useful for investigating incidents that are difficult to reproduce, validating complex migrations, or evaluating behavior against authentic distributions. It also concentrates risk: it may carry sensitive information, include operational secrets, and become outdated quickly.
Reserve this approach for cases where alternatives cannot provide the required level of realism. Define which fields will be extracted, who authorizes preparation, where the copy is stored, who can access it, and when it will be deleted. A copy should not become the default simply because it is convenient.
How to choose based on the test and the risk
Use these criteria to make an explicit decision:
- Development and unit testing: Prioritize small, predictable synthetic datasets that are easy to reset. They should cover valid and invalid values, as well as the boundaries of the rules being tested.
- Integration testing: Combine synthetic data that is consistent with the contracts of connected systems. If a dependency requires historical realism, consider a limited, transformed extract.
- Load or performance testing: Reproduce the necessary volume, distribution, and relationships. Do not assume real identities are needed; check whether synthetic generation can achieve the same operational profile.
- Incident investigation: Start by reproducing the issue with synthetic data. If that is not enough, use a controlled copy with a defined scope, access rules, and expiration date.
- Demonstrations: Curated synthetic data is usually appropriate. Make sure a public or shared demo does not inherit real records, comments, or attachments.
Sensitivity matters too. The more sensitive the information and the broader the access, the stronger the case for synthetic data or a transformation that removes unnecessary detail. The decision should document why the additional realism justifies the effort and risk.
Representativeness, edge cases, and reidentification
Representativeness does not mean reproducing every record. It means preserving the properties that affect the test. Identify dimensions such as status frequency, size distribution, relationships between entities, age, and missing values. Then compare the test dataset against those dimensions without including fields that are not used.
Include uncommon cases that could break assumptions: duplicate records, incomplete sequences, unexpected formats, time zones, or unusual status transitions. Synthetic data makes it possible to create these cases deliberately, while a production sample may not contain them.
To assess reidentification risk, ask what could be inferred by combining retained fields with information available elsewhere. Review direct and indirect identifiers, rare values, and links between tables. If you cannot justify why an attribute is necessary, remove or generalize it, then check again that the test case remains useful.
Controls for the dataset lifecycle
Protection does not end when a dataset is created. Define simple, verifiable controls for its preparation and use:
- Inventory: Identify each dataset, its purpose and source, its fields, and the environment where it will be used.
- Minimize: Extract only the required records and attributes. Keep test data separate from credentials, tokens, and operational secrets.
- Restrict access: Assign permissions according to work requirements and review who can download, copy, or export the data.
- Manage updates: Document how each version is generated, who maintains it, and which schema or rule changes require regeneration.
- Set an expiration date: Define when the dataset and its working copies will be deleted, including known exports.
- Check the result: Verify that it contains no unexpected real data or sensitive fields and that it still covers the intended scenarios.
A reusable test dataset should have an owner and a purpose, just like any other team asset. If nobody knows where it came from or when it should be retired, treat it as operational debt and decide what to do with it before it spreads further.
Common mistakes and a checklist
Two extremes often fail. The first is using real data for convenience: it saves initial preparation time but multiplies copies and makes access and deletion harder to control. The second is using artificial data that is too clean: it reduces exposure but creates false confidence if it does not reflect relevant formats, relationships, and edge cases. The answer is not to choose fidelity or safety absolutely, but to tailor the dataset to the question being asked.
Before approving data for a non-production environment, check:
- Is the test objective defined, along with the data characteristics it requires?
- Can synthetic data meet the need? If not, which aspect of realism is missing?
- Have fields, records, and relationships been reduced to what is strictly necessary?
- Have rare values and combinations that could enable reidentification been reviewed?
- Are access, storage location, updates, ownership, and a deletion date defined?
- Does the dataset cover edge cases, and can it be regenerated when the product or schema changes?
The strongest decision links each type of data to a testing need and a specific control. Start with synthetic data, move to a transformation or controlled copy only when there is a demonstrable gap in fidelity, and revisit the choice when the purpose, data, or access changes.