

An automation can perform well in isolated tests and still fail when it encounters the real variability of an operation. Shadow mode reduces that risk: the system receives the same data as the active process, produces a recommendation or decision, but takes no action affecting customers, orders, accounts, or operational records.
Its purpose is not to prove that automation “works” based on a generic accuracy rate. Its purpose is to determine whether it makes sufficiently sound decisions under the specific conditions and consequences of the process being changed. This applies to request classification, incident prioritization, anomaly detection, document validation, case routing, or recommendations for service and operations teams.
The useful result of a shadow test is not just a percentage of agreement. It is a well-founded operational decision: activate with limits, extend the test, correct data or rules, retain human oversight, or discard the use case.
What shadow mode is and the problem it solves
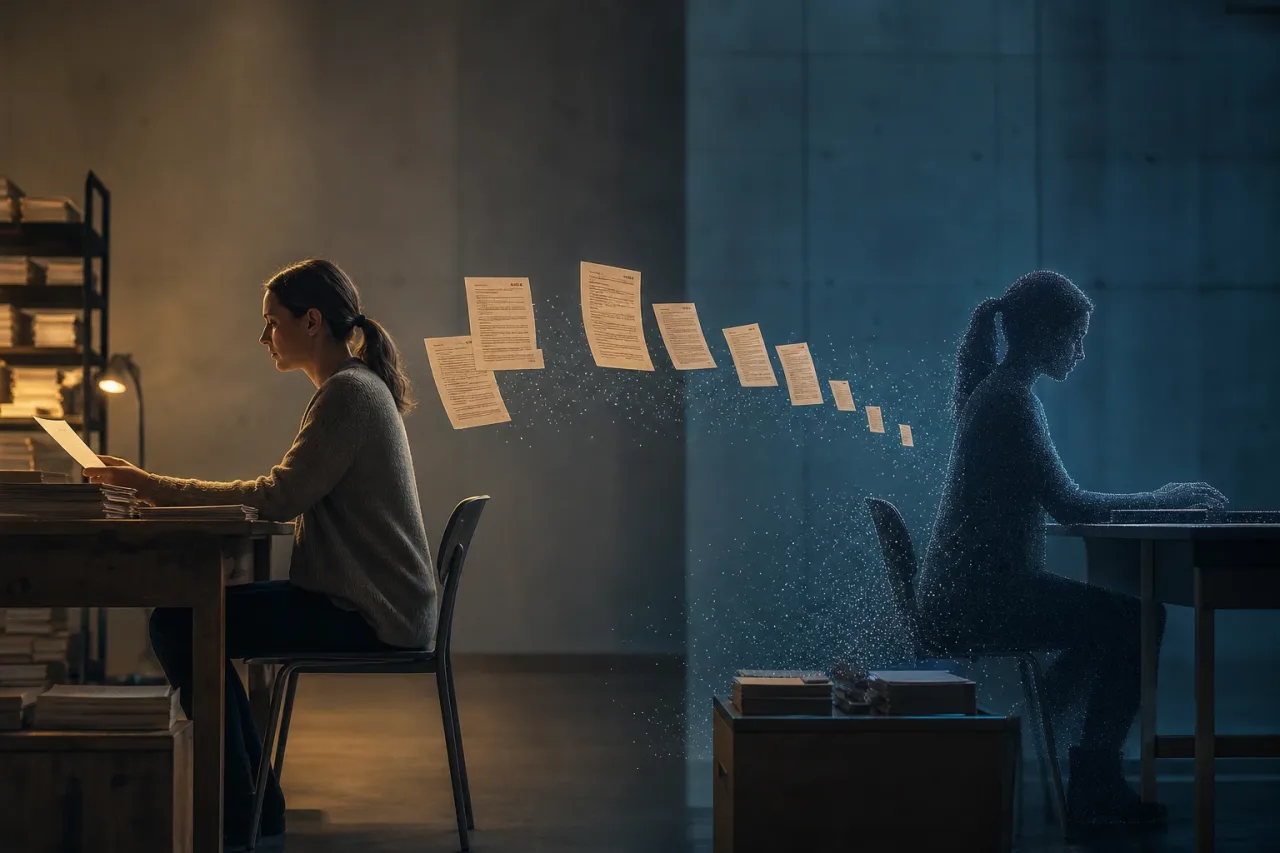
In shadow mode, the automation processes real events alongside the current workflow. The team continues to work with the existing decision, usually made by people or based on approved rules. The automated output is recorded separately for later comparison, without being able to alter the actual outcome.
For example, a system may suggest a priority for every incoming request while the operations team retains the effective assignment. After a period of time, the organization can analyze where the two decisions align, where they differ, and, most importantly, what would have happened if the automated recommendation had been followed.
The separation between recommending and acting must be technical and verifiable. It is not enough to state that the system is “not connected.” The integration must explicitly prevent the shadow output from sending communications, updating statuses, creating tasks, changing inventory, or triggering payments. An accidental write turns validation into an uncontrolled deployment.
This approach aligns with risk management: identifying the context of use, measuring relevant outcomes, and establishing controls before expanding an automated decision. NIST’s AI Risk Management Framework provides a useful structure for organizing these practices. For data quality, provenance, and definition, DAMA International principles help prevent a comparison from appearing conclusive when its reference is inconsistent.
When to use it and when it is not enough
Shadow mode is especially valuable when there is a repeatable decision and a reasonable operational reference against which to compare it. It does not require people to be infallible, but the current process must leave enough traceability to understand what was decided and why.
- Suitable cases: ticket classification, queue prioritization, team assignment, duplicate detection, eligibility checks, and suggested responses or next steps.
- Favorable signals: structured or accessible inputs, an observable outcome, sufficient volume, a history of decisions, and the ability to stop the automation without affecting business continuity.
- Appropriate impact: recoverable errors or decisions that can initially be presented as recommendations reviewed by a person.
However, a shadow test does not eliminate every risk. It is insufficient if the real decision depends on information the system does not receive, if there is no stable human criterion, or if cases are handled so differently across operators that the “truth” is not defined.
It also requires caution for irreversible or high-impact decisions. If a decision affects rights, access to services, safety, payments, or contractual commitments, historical agreement alone does not demonstrate that automation is acceptable. Such cases need additional controls, specialist review, and stricter limits on use.
Define the decision case before building the comparison
A test often fails because it attempts to assess an automation that is too broad, such as “manage requests” or “improve prioritization.” Turn that objective into a specific decision unit. Each record being compared should answer the same question within the same time horizon.
- Input: what data was available at the time of the decision and what data is excluded.
- Output: the category, priority, route, validation, or recommendation generated by the system.
- Real reference: who made the current decision, when they made it, and where it is recorded.
- Consequence: the harm caused by a false positive, false negative, delay, or incorrect routing.
- Timeframe: how long the decision can take before it loses operational value.
- Owner: who reviews results, resolves disagreements, and authorizes changes.
It is advisable to retain a snapshot of the input data, the rule or model version, the timestamp, and the case identifier. Without these elements, a discrepancy cannot be reproduced, and it is impossible to know whether a variation came from the system, a data update, or a change in the human process.
One essential rule is to avoid information leakage. The automation must use only data available before the real decision. If it incorporates a field completed after resolution, the evaluation will look artificially strong and will not represent production performance.
Design a parallel run that does not alter operations
The technical design should support isolation and auditability. The shadow workflow can consume a copy of events or read information from a controlled source, but its results must go to a destination separate from the transactional system.
operational event → current process → real action
operational event → shadow automation → evaluation record
Before starting, test simple but decisive safeguards: credentials without write permissions where possible, separate queues or tables, visible labels for evaluation records, and alerts for any attempt to take an external action. If an integration needs access to production systems, apply least privilege and review which fields it receives and retains.
The comparison must join the same case across both workflows. Define a stable identifier and a rule for determining when a human resolution is final. If the team reclassifies a request several times, recording only the final status can conceal material delays or corrections. At a minimum, retain the initial recommendation, the initial real decision, and the case outcome.
What to measure and how to investigate disagreements
Agreement is a starting metric, not a verdict. Two decisions may match on category while differing materially in urgency, owner, or deadline. A discrepancy may also reveal an automated error, an ambiguous human rule, or missing data.
Organize the analysis around indicators that address real risks:
- Weighted agreement: do not treat a difference between two nearby priorities the same as omitting a critical case.
- Outcome quality: review reopenings, escalations, missed deadlines, corrections, and rework when applicable.
- Decision time: measure whether the suggestion arrives within the useful window, not only whether it is eventually correct.
- Coverage: identify the proportion of cases it processes and which it rejects or leaves without a recommendation.
- Exceptions: group outcomes by channel, request type, period, incomplete data, and other relevant operational segments.
Review disagreements through a qualitative sample, prioritizing those with the greatest impact. Classify them into actionable categories: data error, unexpressed business rule, missing input information, inconsistent human decision, system error, or legitimate process variation. Do not correct the system merely to imitate every human decision. If a real decision was poor or contradictory, turning it into the target only institutionalizes the problem.
The sample should include frequent cases as well as edge cases: demand peaks, shift changes, incomplete submissions, duplicates, urgent cases, and periods involving policy changes. A test based only on averages may hide precisely the failures that create the greatest cost or risk.
Practical criteria for activating, expanding, or redesigning
Define exit criteria before looking at the results. This avoids lowering the threshold afterward to justify an investment already made. Thresholds should relate to the cost of error, oversight capacity, and initial scope, not to a universal figure.
Consider an automation that prioritizes requests. It may first be activated as a visible recommendation if it maintains acceptable quality for critical cases, covers the ordinary flow, and allows the team to override it easily. It may then be expanded to automated decisions only for low-criticality requests, while retaining human review for urgent cases or incomplete data.
- Activate with limits when serious disagreements are infrequent, explainable, and controllable, and alerts and a clear rollback are in place.
- Extend the test when representative periods, segments, or exceptions are still missing, even if the initial result is promising.
- Correct and repeat when data-quality issues, ambiguous definitions, or rules the process has not yet formalized are the prevailing problems.
- Retain human oversight when automation adds speed or consistency, but the risk of certain exceptions still requires expert judgment.
- Discard or redesign when there is no reliable reference, the cost of error exceeds the expected benefit, or the process must be simplified before it can be automated.
Shadow mode adds value when it is treated as a decision practice rather than a technical demonstration. Isolate actions, compare against relevant operational outcomes, investigate differences, and limit deployment according to the evidence. This allows automation to reach production with explicit controls and a real understanding of where it helps, where it needs oversight, and where it should not make decisions.