

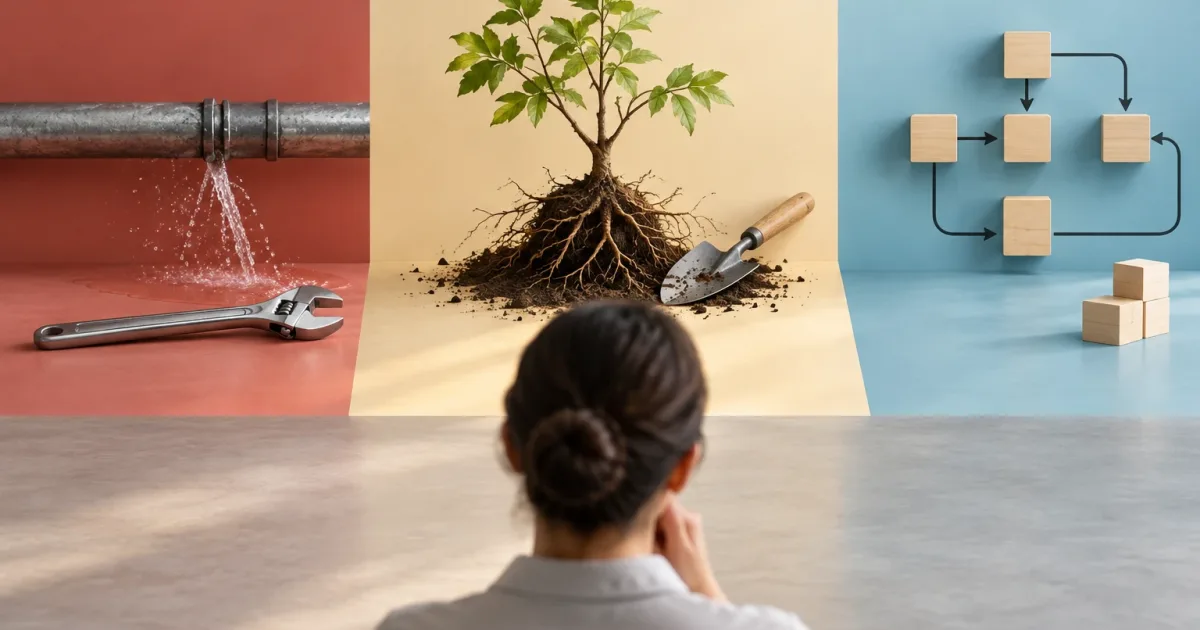
When an incident happens again, the quickest response is not always the best one. Fixing the individual case may restore service while leaving the cause untouched. At the other extreme, redesigning an entire process to prevent an isolated problem consumes resources and may introduce new risks. A useful decision depends on distinguishing the symptom, measuring the scope, and choosing a proportionate intervention.
This framework helps product, technology, and operations leads choose among three responses: resolve the case, eliminate a technical cause, or change how the work is done. You do not need to wait until you have all the data; you should, however, record what is known, make uncertainties explicit, and establish how you will check the result.
Separate the symptom from the cause
An incident is the visible event: an operation is left incomplete, a data point does not match, or a task requires manual intervention. The cause is the mechanism that makes that outcome possible. It may be a software defect, an integration, an ambiguous rule, a poorly handled exception, or a combination of factors.
Before choosing a solution, describe the problem in observable terms:
- What happened: what was the incorrect outcome or blockage?
- Where and when: which step, system, or condition was involved?
- Who or what was affected: which people, operations, data, or services were involved?
- What evidence exists: logs, messages, inputs, or reproducible sequences.
- What is still unknown: hypotheses that need to be checked.
Avoid turning the first plausible explanation into a diagnosis. For example, the fact that someone entered incorrect data does not prove that an individual mistake was the cause: the label may have been confusing, validation may have been missing, or instructions may have conflicted. A good investigation asks what conditions allowed the outcome, not just who performed the final step.
Classify before investing effort
Assess each incident against four criteria. You do not need to create a sophisticated scoring system at first; simply record the criteria and compare cases consistently.
- Frequency: is this an isolated case, does it recur under a specific condition, or does it appear in different parts of the operation?
- Impact: what are the consequences for customers, revenue, compliance, data quality, workload, or service continuity?
- Scope: does it affect one person or transaction, a segment, several teams, or the entire workflow?
- Reversibility: can the fix be safely undone if it proves wrong? Could it have lasting effects on data or subsequent decisions?
Also consider how confident you are in the diagnosis. A high-impact incident with an uncertain cause may first require containment and evidence gathering. By contrast, a reproducible, limited failure makes it possible to assess a permanent fix sooner. Separate urgency from a definitive solution: containing a risk immediately does not mean the underlying problem is resolved.
When a quick fix is enough
A quick fix is usually reasonable if the case is exceptional, its impact is limited, the cause appears circumstantial, and the outcome can be repaired safely. It might involve completing an operation, restoring a value, or applying an authorized exception. The key condition is that the intervention must not conceal a pattern or create invisible operational debt.
Record each case using a shared category, date, context, impact, action taken, and reference to the available evidence. Also note whether the cause is confirmed or remains a hypothesis. If every team describes the same problem differently, recognizing recurrences will be harder; a short, shared taxonomy helps group them.
When making a correction, check dependencies: if other processes consume the affected data or outcome, a local repair may leave inconsistent states behind. Keep a review path and specify who can authorize exceptions. If the case recurs, a quick fix is no longer a sufficient strategy, even if it remains necessary to address each occurrence.
Signs that you need to eliminate a root cause
Look for a permanent solution when incidents share a mechanism, recur under known conditions, generate repeated manual work, or expose an unacceptable risk. In software, the response might be to fix a validation rule, handle an unexpected response correctly, or strengthen an integration. In operations, it might mean clarifying a rule or preventing a transition that allows incomplete data.
A permanent intervention should address a verified cause, not merely the most frequent symptom. Before implementing it, define:
- The causal hypothesis and the evidence that supports it.
- The smallest change that can prevent or detect the failure.
- The workflows, data, and users that could be affected.
- A test of the original case and nearby scenarios that should continue to work.
- A rollback or containment mechanism in case side effects appear.
If you still cannot explain why the incident occurs, invest first in observability or reproduction. Adding an alert can help detect the problem, but it does not eliminate it. Similarly, a code change that blocks one specific case could conceal a poorly defined business rule. The solution should address the expected behavior, including relevant limits and exceptions.
When to change the process, not just the system
The source may lie in the rules, responsibilities, or sequence of work. Suspect a process problem if different tools show the same failure, each team applies a different interpretation, exceptions depend on informal knowledge, or the error occurs during a handoff between teams.
In that case, review who decides, who carries out, and who verifies each step. Clarify entry and exit conditions, remove duplication, and specify what to do when a condition is not met. Do not turn every variation into another form or approval: each control also costs time and may shift the problem elsewhere. Consult the people doing the work, because they often know about exceptions that a formal diagram does not capture.
Process changes require communication and follow-up, not just documentation. Where practical, test the new way of working in a limited workflow, gather questions, and adjust instructions before rolling it out more widely. If the process requires manual steps to compensate for a technical limitation, record that dependency. It may be a temporary decision, but it should have an owner and a review criterion.
Decision matrix and outcome review
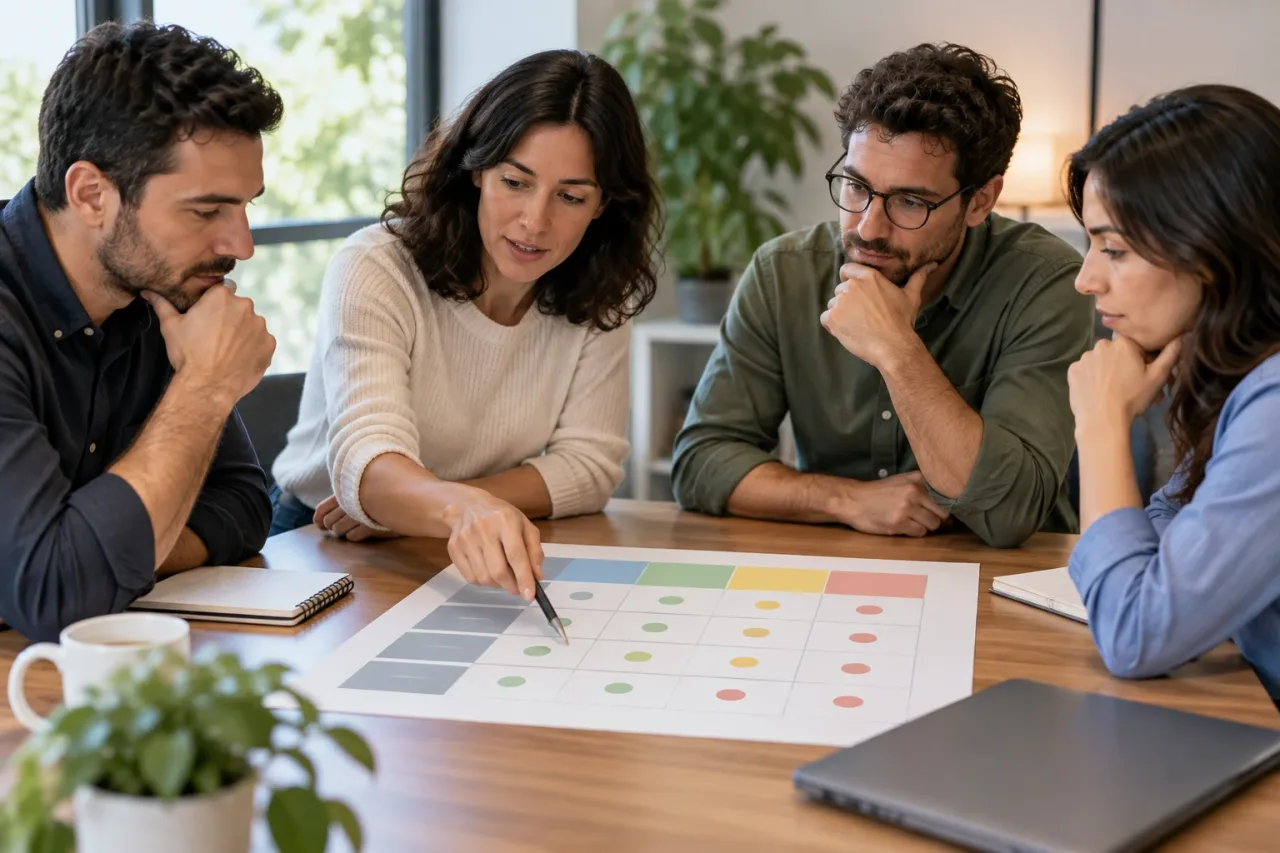
The following matrix is a starting point, not a substitute for team judgment. The examples are hypothetical and should be validated against the actual context.
- One isolated case, low impact, and a reversible repair: fix the case and record the context so you can detect repeat occurrences.
- A reproducible pattern in a system or integration, with known scope: contain the effect and prioritize eliminating the technical cause, including regression tests.
- Different outcomes depending on the team, or an ambiguous step: review the rule, responsibilities, and sequence before automating the response.
- High impact or data that is difficult to restore, with an uncertain cause: limit exposure, escalate the investigation, and avoid irreversible changes until you understand the dependencies.
Before making a change, define which signal will confirm an improvement: fewer cases in the same category, fewer manual corrections, shorter resolution times, or fewer affected operations. Use an observation period suited to the pace of the process and compare equivalent conditions; a temporary decline may reflect lower activity rather than a successful solution.
Also check for signs of collateral damage: legitimate rejections, new errors, delays, additional handoffs, or more exceptions. If recurrence falls but manual work increases, the measure may have shifted the cost rather than solved the problem. Then decide whether to keep, adjust, or remove it, and record the decision. Periodically reviewing grouped incidents can reveal when a quick fix has become a pattern and warrants a broader response.
In short, fix the case when it is exceptional and manageable, eliminate the cause when the mechanism is identified, and change the process when rules or handoffs are the source. If the diagnosis is still weak, contain the risk and gather evidence before committing to a solution that is difficult to reverse.