Choosing how to persist an application's data is more than a storage decision. It determines what you can reconstruct, how you explain changes, and how much effort it takes to maintain the system. Event sourcing stores a sequence of events as the source of truth; a traditional model usually stores the current state and, when needed, a supplementary history.
Neither option is better in every situation. The useful question is when a complete history and the ability to reconstruct state provide enough value to justify a more demanding architecture. This guide offers practical criteria to help you decide, identify simpler alternatives, and start with a controlled scope.
What event sourcing means and how it differs from a traditional model
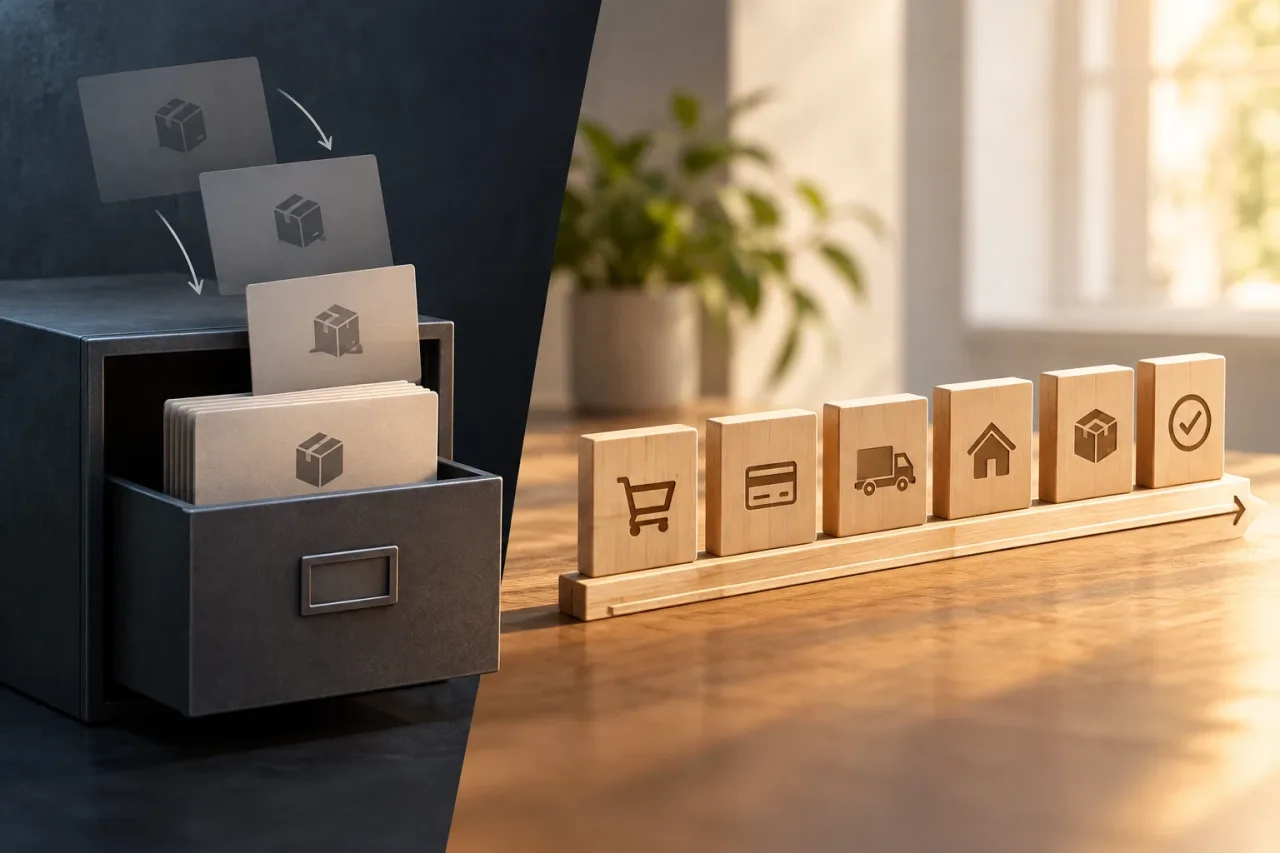
With event sourcing, an application records business facts that have already happened, such as OrderCreated, PaymentConfirmed, or AddressUpdated. The current state is obtained by applying those events in order. Instead of overwriting a row with the latest value, the system retains a sequence that describes how an entity evolved.
In a traditional model, the database usually contains the current version: for example, an order's current status and amount. An update replaces previous values. If you need to know who changed a value, when it changed, or what it used to be, you can add an audit log or a purpose-built history.
The decisive difference is not that one approach has a history and the other does not. It is which record is authoritative. With event sourcing, events are the source of truth, and current views are derived from them. In a traditional model, the persisted state is usually authoritative; any history serves an additional purpose.
Start with the problem, not the architecture
Before choosing, define the business question you cannot answer today. “We want more traceability” is too vague; “we need to reconstruct which decisions produced an account balance on a particular date” describes a testable need. That precision lets you compare solutions without adopting an architecture simply because it seems technically appealing.
- History: You need to look up earlier changes, but not necessarily reconstruct the entire state. An audit log may be enough.
- Reconstruction: You need to recalculate state from retained facts, for example to correct a business rule or analyze a historical situation.
- Traceability: You need to explain what happened and in what order. Business events or a history designed for this purpose may meet the need.
- Current queries: Most screens only need to read the current state. A traditional model may offer a more direct path.
It is also worth checking whether the requirement is permanent and central to the product, or confined to a single process. Event sourcing makes more sense when the sequence of changes is an essential part of the domain, not merely because someone wants to “save everything.”
Practical criteria for making the decision
Evaluate each criterion against real examples from your domain. They do not all need to point to event sourcing, but you should understand which requirement is driving the choice.
- Changes have meaning of their own: “reservation confirmed” or “refund approved” are significant facts, not simple field updates. This favors modeling explicit events.
- Reconstruction is necessary: The business needs to recover earlier states or recalculate them using new rules. If you only need to show the latest changes, a history may be sufficient.
- Order matters: The sequence of actions determines the result, and the team needs to retain that sequence reliably.
- There are several views of the same process: Different teams or functions need to query the same facts in different ways. Projections can support those reads, although they add work.
- The domain includes corrections and exceptions: These must be represented as new facts—for example, a correction or reversal—rather than silently erasing what happened. Define the meaning of each event carefully.
If the need is limited to updating records and querying their current version, a traditional model will probably be simpler. If the history must be complete, understandable, and usable to derive states, event sourcing merits a closer evaluation.
Costs, risks, and signs that it may not be the right fit
Storing events does not eliminate complexity; it shifts it. Reads often depend on projections, meaning derived views that are updated from events. If these are processed asynchronously, eventual consistency may result: for a period, a read reflects an earlier state. The product must be able to tolerate that or define how to present and handle the delay.
Persisted events also cannot be edited like ordinary rows. As the domain changes, you need to decide how to interpret old events, how their formats evolve, and how projections are rebuilt. You also need procedures for detecting processing failures, replaying events safely, and maintaining operations and support. An incomplete or poorly defined sequence can undermine the very reconstruction you set out to enable.
Consider rejecting or postponing event sourcing if the team cannot explain which events represent business facts, if the required queries are simple, or if the system does not need reconstruction. It is also a warning sign if the main argument is “we need an audit trail,” without requirements for historical queries, retention, or how that record will be used. In those cases, a well-designed history table may meet the goal with fewer moving parts.
Hypothetical example: orders with changes and corrections
Imagine an application that manages orders. The team needs to display the current status, amount, and address. A traditional model with order data and a change history may be enough if the goal is to query the current version and explain recent modifications.
The decision changes if the business needs to reconstruct how the amount was calculated, distinguish confirmations from corrections, and recalculate historical situations using new rules. Event sourcing could record facts such as order created, payment confirmed, and amount corrected. The order view would be derived from that sequence. But the team would need to decide how to represent a correction, how to handle old events, and which reads might temporarily show stale data.
This example does not mean every order process needs event sourcing. The choice depends on verifiable requirements: what must be reconstructed, who queries the history, and how much complexity the team can operate.
Questions to check before adopting event sourcing
- What specific question cannot be answered using the current state and a simple history?
- Which entities or processes need to be reconstructed, and for what business purpose?
- Do the events describe facts with stable meaning, or do they merely copy technical field updates?
- Which views need to be maintained, who uses them, and how much delay can they tolerate?
- How will you handle corrections, duplicate events, format changes, and reprocessing?
- Who will be responsible for monitoring projections and resolving processing failures?
- Is there a simpler alternative that meets current requirements without closing off future options?
Start small and revisit the decision
If the requirements justify event sourcing, limit adoption to a process whose history has clear value. First define the event vocabulary with domain stakeholders and agree on what each event guarantees: what happened, what data is needed to interpret it, and what must not change afterward. Design the primary queries and projection recovery process before expanding the scope.
Record the decisions and revisit the architecture when needs change. If the product no longer requires reconstruction, or the cost of maintaining projections exceeds their usefulness, simplifying may be reasonable. If new traceability and analysis requirements emerge, a conventional history may no longer be enough. The best choice is the one that meets real needs and the team can operate reliably, not the one that adds the most mechanisms in advance.