

An automated classification should not be accepted simply because the model assigns it a high score. That score is a system estimate, not a guarantee that the category is correct or that the decision is appropriate for the process. Deciding what to do with each result means combining prediction quality with the cost of getting it wrong, the possibility of review, and the operational consequences.
A practical framework divides results into three paths: automatic acceptance, human review, and rejection or referral to an alternative process. The boundaries between these paths can vary by category and change over time. The goal is not to maximize automation at any cost, but to automate cases that are safe enough and make cases requiring attention visible.
A confidence score is not a decision
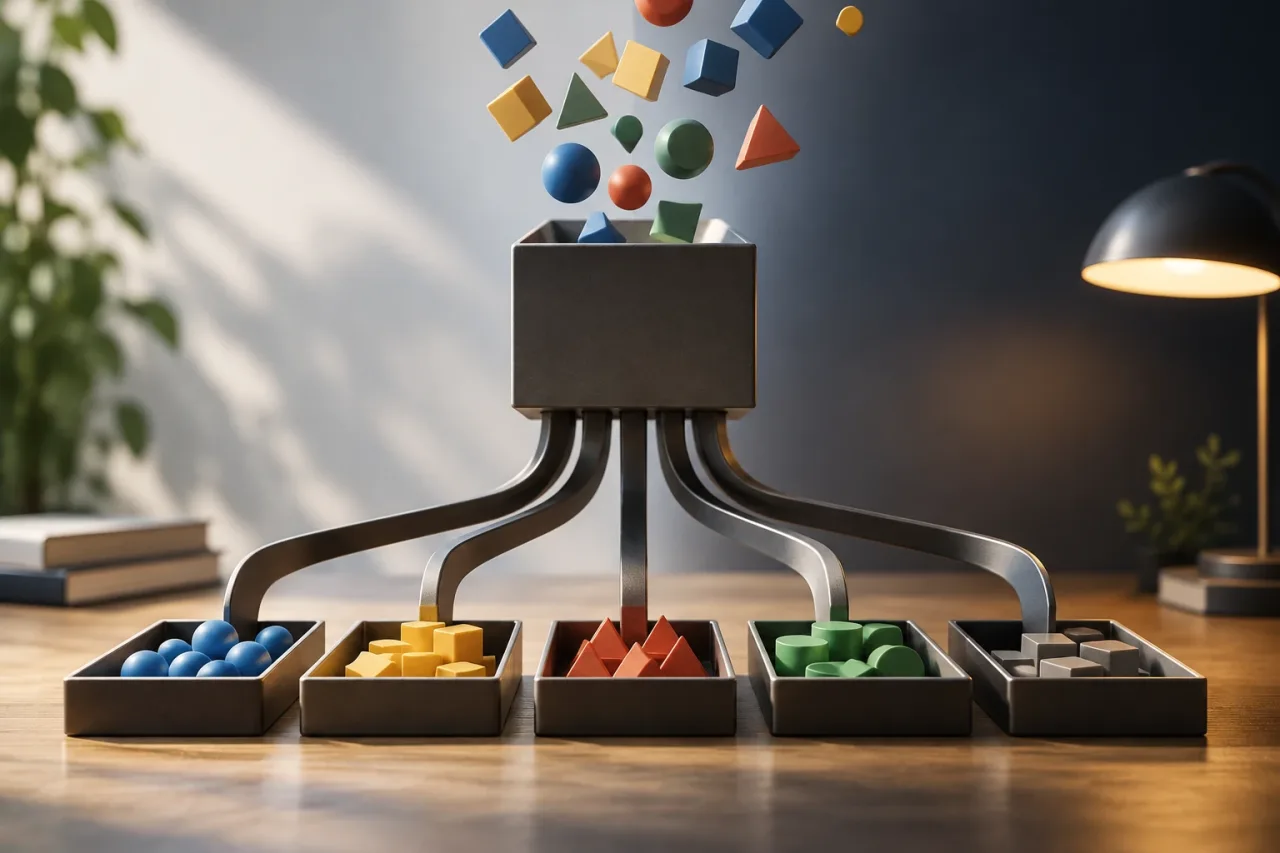
Classifiers can return a category and an associated score. However, a score of 0.9 does not necessarily mean that the result has a 90% probability of being correct in the specific use case. Its interpretation depends on how the model was trained and evaluated, how representative the data is, and whether the scores are calibrated.
In addition, the same score can imply different risks. Classifying an information request as “general” rather than “billing” may cause a minor delay; classifying an urgent request as routine can have more serious consequences. Therefore, do not set a single threshold for all classes without first analyzing the cost of each type of error.
Before automating, check what the available score means, how it performs on representative data, and whether the model can abstain when it cannot find a sufficiently clear answer. If the score is not calibrated, use it as a signal for ranking or prioritization, not as an exact probability.
Calculate the cost of errors by category
For each class, compare two errors: a false positive, when the system assigns a category that does not apply, and a false negative, when it fails to detect a category that does apply. In a multiclass classification, specify which confusions are actually harmful; not all incorrect categories have the same impact.
A class-by-class confusion matrix can help identify frequent errors, but metrics do not replace an analysis of the workflow. Ask operations teams what happens after each label: Is a message sent? Is a case assigned to a team? Is a priority triggered? Is a document archived? Record the impact in practical terms, such as rework, delay, failure to follow a procedure, or risk to the person affected, without assuming that every error has a known monetary cost.
- Reversible, low-impact errors: broader automation may be reasonable if there is a straightforward way to correct them.
- Errors that are difficult to detect or correct: require more conservative thresholds and additional controls.
- Classes with significant consequences: may need human review even with high scores, depending on the process policy.
The result is a policy for each class: which errors are tolerable, which require review, and which require automation to stop or be referred elsewhere.
Divide outputs into accept, review, and reject
Set two score thresholds rather than one. Above the upper threshold, the system can propose automatic acceptance; between the two, the case goes to review; below the lower threshold, the automatic prediction is rejected or sent down an alternative path. In this context, “reject” means not using the classification as the final decision, not discarding the person's request.
The thresholds do not have to be the same for every class. If confusing two categories has different effects, you may need different thresholds or specific rules for those confusions. You can also require an additional condition, such as the most likely category exceeding the second-most likely by a minimum margin. That separation can help identify ambiguous results, although it should be evaluated using data from the workflow itself.
Document each path clearly: who can correct a result, what happens when the system does not respond, and how the final decision is recorded. A low-confidence output must have a defined operational destination; otherwise, the team will end up inventing exceptions case by case.
Calibrate with representative, verified examples
Gather examples that reflect real use: common and infrequent categories, short and long texts, different formats, ambiguous cases, and foreseeable input errors. Include samples from the channels and groups that will feed the system. A dataset made up only of easy cases can make performance appear better than it will be in production.
For each example, record the correct label using agreed criteria and establish how disagreements will be resolved. Keep the data used to adjust the policy separate from the data reserved to check it. For each possible threshold, measure at least how many cases would be accepted automatically, what proportion of those cases is correct by class, and how many would go to review. Also assess errors according to their operational impact.
- Define the classes and the consequences of each error with the people responsible for the process.
- Build a representative sample and verify its labels, resolving any disagreements.
- Test several thresholds and calculate precision, automatic coverage, and review workload by class.
- Choose the policy that meets risk and operational capacity requirements, not just an aggregate metric.
- Validate the decision on separate data before applying it in production.
The NIST AI Risk Management Framework offers a reference for organizing risk identification, assessment, and management. It does not provide a universal threshold to copy: the decision must reflect the context, data, and impact of the specific system.
Design human review as part of the product
Review is not a technical exception that can be handled by sending cases to an inbox. Define who reviews them, what information they need, how much time they can spend, and what actions they can take. Show the suggested category and relevant context, while allowing reviewers to correct it, request information, or escalate the case when the policy requires it.
Record the final label and, if possible, the reason for the correction. These data help identify recurring confusions and prepare improvements; they should not be incorporated into training automatically without quality controls. If reviewers do not share consistent criteria, their decisions may add noise rather than reduce it.
Monitor the workload, too: a very high review rate can turn automation into a bottleneck. If volume exceeds expected capacity, prioritize by impact, urgency, or age, and review whether the model, categories, or thresholds need to change. Do not loosen thresholds on the fly just to reduce the queue.
Monitor and review the decision policy
Measure results by class and by relevant process segments. At a minimum, track the precision of automatic acceptances, the review rate, the percentage of rejections or referrals, significant errors, and resolution time. An overall metric can hide systematic failures in a minority category.
Compare predictions with verified outcomes and set a review frequency suited to the risk and volume. Reassess the policy if categories, forms, channels, the model, or operational rules change. Also investigate signals such as an increase in human corrections, a shift in the class distribution, or more cases outside known patterns. These are indications to analyze, not automatic proof that the model has deteriorated.
Keep versions of the thresholds, the evidence used to approve them, and the review date. Data management and data quality also matter: inconsistent definitions or outdated labels weaken any calibration. DAMA International’s Body of Knowledge can serve as a general reference for structuring data management practices.
Checklist for getting started
- Does each category have an operational definition and boundary examples?
- Have false positives and false negatives been compared according to their consequences?
- Do the thresholds distinguish acceptance, review, and referral, and can they vary by class?
- Does the evaluation use representative data and verified labels?
- Is there human review capacity, guidance for reviewers, and an escalation path?
- Are errors, coverage, and review workload measured by class?
- Are there owners, records, and explicit conditions for reassessing the policy?
In short, setting confidence thresholds means designing a decision policy, not choosing an isolated number. Start with the cost of errors, validate thresholds using real cases, and maintain a safe path for uncertain results. This allows automation to grow without confusing a model score with a reliable decision.