

Deploying an application in multiple regions can seem like a straightforward way to reduce outages or bring a service closer to its users. But distributing infrastructure also introduces new decisions: how data is replicated, what happens if a region becomes isolated, and who can operate the system. The question is not how many regions are possible, but what specific problem a second region would solve and whether the team can sustain the solution.
The decision depends on service objectives, dependencies, and the consequences of an outage. A simple, well-monitored architecture with tested recovery may be more appropriate than a multi-region setup no one has rehearsed. This guide sets out criteria for comparing options and moving forward gradually.
What it means to deploy in one region or several
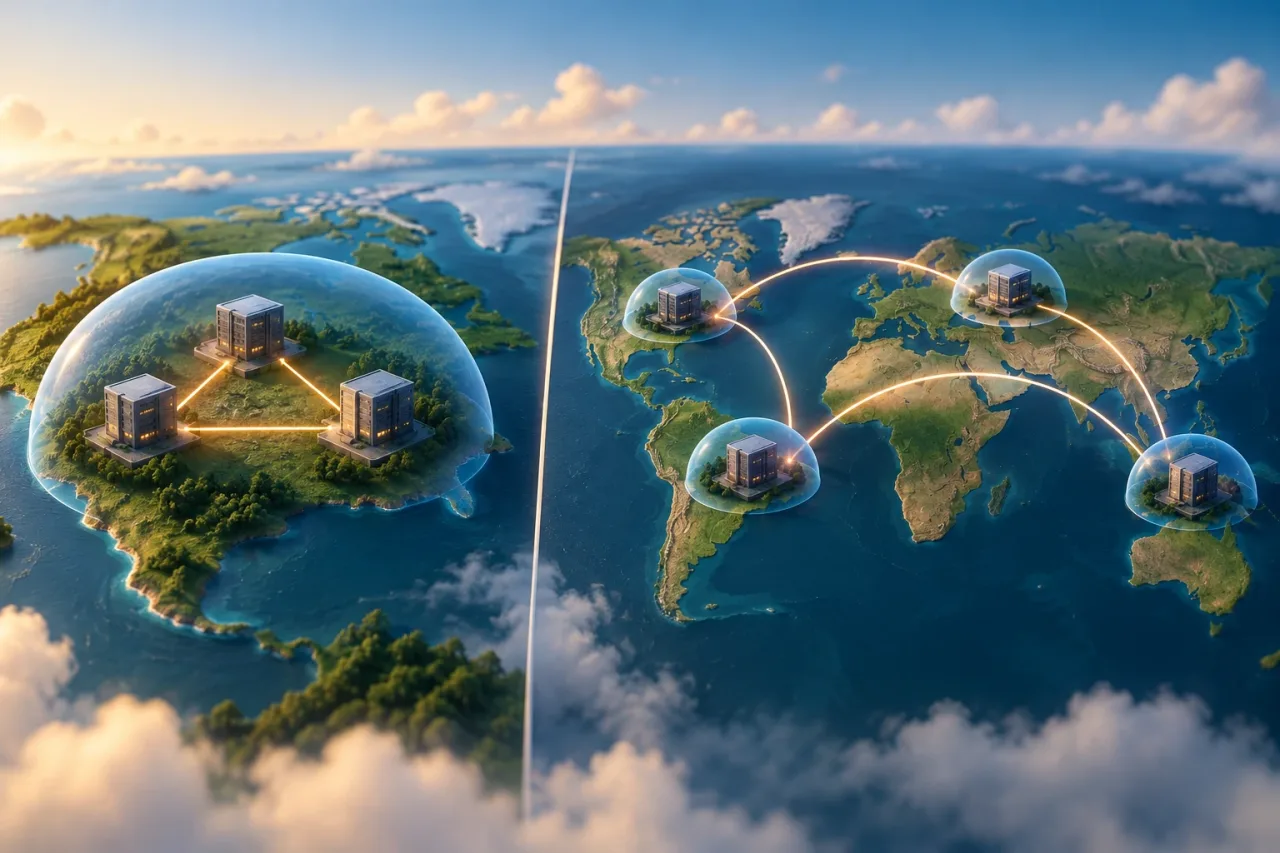
A region is a geographic location within cloud infrastructure. An application deployed in a single region concentrates its main components there, although they may be distributed across different availability zones. Multiple zones within a region help mitigate certain local failures, but they are not the same as having a second region ready.
In a multi-region deployment, application components operate or can operate from different geographic locations. Configurations vary: one region may handle normal traffic while another stands ready for recovery, or both may be active and receive requests. These options do not have the same data, routing, or operational requirements.
It helps to define the scope first. An application may have servers in several regions and still depend on a database, identity system, or integration that works in only one. In that case, distributing the application layer does not mean the entire service can continue if a region is lost.
Identify the problem before choosing an architecture
The most common reasons to consider multiple regions fall into three groups. Each calls for different tests and decisions:
- Continuity: keeping the service running or restoring it if a region becomes unavailable. Specify how long an interruption can last and how much data could be lost or need to be reconstructed.
- Latency: reducing response times for geographically dispersed users. The benefit depends on where users are and whether critical operations can be handled locally, including their data and dependencies.
- Data location: meeting requirements for data residency, processing, or access. Hosting copies in different locations may complicate rather than resolve applicable obligations; these must be checked for each data type.
Making the objective measurable helps avoid adopting a solution based on intuition. For continuity, agree on recovery objectives for the service and its data. For latency, measure actual user paths. For data residency, identify which data must remain in which location and which components process it.
When one well-operated region may be enough
A single region may be sufficient when the impact of an outage is manageable, users are concentrated in one area, or current latency meets the product’s needs. It may also be the more sensible choice if the team does not yet have processes for testing and operating a second location.
Before adding regions, review the resilience measures available within the current architecture. These may include redundancy across zones, backups, documented restoration, dependency monitoring, and a reversible deployment strategy. A backup provides protection only if it can be restored and the result has been verified as suitable for recovering the service.
Investigate previous incidents and outages: were they caused by a regional failure, a software change, an external dependency, or a configuration issue? If the main risk is not regional, adding another location could increase the workload without addressing the cause. Also record how long manual recovery would take and which tasks still depend on a particular person.
Costs and risks of distributing a service
Multi-region complexity is not limited to maintaining more resources. The application may require decisions about replication, conflict resolution, operation ordering, and behavior during a loss of connectivity. If two locations accept changes to the same information, the design must specify which is the source of truth and how simultaneous writes are handled.
Consistency is a product and architecture decision. A delay in replicating information may cause a user to see an outdated state or two operations to conflict. This may be acceptable in some cases, but it is unwise to assume every feature can tolerate that behavior. Define which actions require an immediately consistent response and which could temporarily work with delayed data.
External dependencies, identity management, queues, storage, DNS or routing, observability, and deployment processes also need review. Each element can become a single point of failure or require region-specific configuration. Operating costs include testing, on-call coverage, incident analysis, and maintaining procedures, in addition to infrastructure.
Assess whether critical paths can operate in each region
Map essential user actions, from the initial request to the final confirmation. For each path, note the services and data involved, where they are located, and what happens if the primary region stops responding. The unit of analysis is the complete journey, not an isolated server.
- Classify features: distinguish those essential to operation from those that can be degraded or temporarily unavailable.
- Trace dependencies: include internal services, external systems, and operational processes that may not appear in the infrastructure diagram.
- Describe failure scenarios: analyze total loss, partial connectivity, and recovery. Clarify who detects the problem and how the traffic change is decided.
- Validate the data: determine which writes must be available, what delay is acceptable, and how duplicates or conflicts would be resolved.
- Check the outcome: verify that user-visible operations complete, not merely that components respond.
This review reveals whether the regions are genuinely independent or whether the second location relies on resources that remain in the first. It also helps prioritize a targeted improvement, such as making a critical dependency recoverable, rather than replicating the entire platform.
Secondary region or active service across multiple regions
A secondary region designed for recovery is generally focused on restoring service if the primary region fails. The team must decide what stays ready, how it is activated, and which data will be available during recovery. Failover may require intervention, so actual recovery times should be tested rather than inferred from the design.
An active multi-region service can handle traffic from more than one location as part of normal operations. This may improve latency or continuity, but it requires decisions about routing, load distribution, and data behavior across regions. It does not necessarily mean every operation is independent or that a failure-triggered change will be automatic and correct.
The choice depends on agreed objectives and operational capacity. If the service can tolerate planned recovery, a secondary region may be enough. If it needs to operate in parallel to meet availability or response-time needs, an active configuration may make sense, provided its data rules and tests are viable.
Decide based on evidence and move forward incrementally
Bring product, technology, and operations together to answer four questions: What would an outage affect? Where are the users and data? What recovery is acceptable? And who can operate and test the architecture? Record assumptions and uncertainties. If a critical question has no answer, that lack of information is a risk to resolve before expanding the deployment.
Then validate the smallest option that enables learning. This might mean measuring latency by location, restoring a backup in a separate environment, or rehearsing recovery for a dependency. If you test a failover, define its scope, owners, start conditions, and success criteria; also review how to return to normal and reconcile data.
Revisit the decision when the user profile, data requirements, impact of an outage, or composition of the service changes. The right architecture is one that meets explicit objectives and that the team can demonstrate it can recover. Multiple regions may be the answer, but they are not an objective in themselves: their value lies in a verifiable improvement over a simpler alternative.