

When a website, app, or integration fails, the problem is not just technical. Users may be unable to complete a purchase, find information, or access a feature they need. Clear communication is part of the response: it helps people understand the impact, reduces uncertainty, and lets them choose an alternative when one is available.
Communicating does not mean publishing every suspicion the team has or waiting until the root cause is known. It means explaining what is known about the service and providing updates as the situation changes. This guide offers criteria for deciding when to notify users, what to include, who should communicate, and how to close the incident without promising more than you can confirm.
Communication is part of the incident response
An incident may be partly resolved from a technical perspective and still be confusing for users. It may also remain unresolved while affecting an important task. In either case, silence leaves people without context and may lead to more enquiries for customer support.
The initial goal is not to explain the entire internal investigation. It is to answer practical questions: which service or feature is affected, who may be affected, what alternative is available, and when the next update will be published. You can share the cause later, once it has been sufficiently verified and would be useful to users.
It is helpful to distinguish an operational alert from a user-facing message. The first may include metrics, alerts, and technical components; the second should translate the service status into understandable consequences. This distinction prevents sharing details that the public cannot interpret or that may still change.
Decide whether to notify users based on impact, not just duration
There is no universal time threshold that applies to every incident. A brief failure can matter if it blocks a critical action, while a limited degradation may not require a general alert if there is a clear alternative and few people are affected. Assess the impact, scope, and users’ ability to act.
- Impact: What task can users not complete? Is access lost, are there errors or delays, or is information displayed incorrectly?
- Scope: Does the issue affect everyone, one region, a type of account, or a specific feature? If this is not known, say so precisely.
- Duration and progression: Is the problem persisting, recurring, or getting worse? An incident that lasts or changes in scope may warrant an alert even if it began as a minor issue.
- Alternatives: Is there another channel, process, or feature users can use to complete the task? Do not describe an alternative as a solution unless it has been checked.
As a practical rule, notify users when they need to make a decision, when the issue affects an important task, or when silence could lead them to repeat an action with consequences. For a limited failure, a targeted notification may be better than an alert to your entire user base. If the scope is not yet known, identify the affected area and avoid claiming that the rest of the service is working normally unless you have verified it.
Separate confirmed facts, uncertainty, and internal details
A useful update distinguishes between what is confirmed and what the team is still investigating. For example, you can confirm that some people cannot complete a transaction even if you do not yet know why. You do not need the technical cause to describe the impact.
Use specific language: “We’re investigating errors when signing in” says more than “We’re looking into an anomaly.” If the information is partial, set clear boundaries: “The issue affects history loading in the mobile app; we’re checking whether other channels are affected.” Avoid absolute terms such as “everyone,” “no one,” or “fully resolved” unless the evidence supports them.
Internal hypotheses, system names, and snippets of team conversations are rarely useful to users. They can also cause confusion or reveal information that should not be published. If a hypothesis changes, you do not need to narrate every turn in the investigation. Update the impact and status using confirmed information.
A good notice can acknowledge uncertainty without sounding evasive: “We haven’t confirmed the cause yet. The team is working to restore the service, and we’ll post another update at 3:30 p.m.”
Choose the channel, audience, and owner
The channel should make the notice accessible to the people affected. Depending on the issue and the available contact methods, this could be an in-product banner, a status page, an email, or a notification. Do not assume one channel will reach everyone: if the product is inaccessible, an in-app notice will not be enough.
Match the audience to the impact. A general message about a failure affecting one specific feature can create noise; targeted communication helps each person receive relevant information. On the other hand, if the issue may affect more users than first identified, widen the notice and explain that the team is still assessing the scope.
Decide in advance who drafts, who reviews, and who publishes the message. Review should check the stated impact, alternatives, and time of the next update—not turn every notice into a lengthy approval process that delays it. Customer support and technical teams need a consistent view of the status, even if each channel uses a different level of detail. Assigning one person to publish helps prevent contradictions and duplicate messages.
Provide updates at a predictable pace and when things change
An initial notice is not enough if the incident continues. Set a time for the next update, even if there is no new information. Keeping that commitment is more useful than promising a resolution time that depends on factors you do not yet know. If the planned update time changes, communicate the change and set a new expectation.
Updates are warranted when the scope changes, a different impact emerges, an alternative becomes available, recovery begins, or a feature is confirmed to be working again. You should also publish an update when the announced time arrives, even if the status is “we’re still investigating.” Do not turn every minor internal change into a notice; prioritise changes that affect what users need to know or do.
Include the time and, when relevant to a diverse audience, the time zone. If several channels are active, keep their status consistent. A status page should not say service has recovered while support is still telling users there is a complete outage.
A concise structure for actionable messages
Most incident communications can be organised around four elements. This structure makes messages easier to scan and keeps them focused on what users need rather than the internal investigation:
- Impact: Describe the failing feature and the task that may be affected.
- Status: Say whether the team is investigating, applying a fix, or checking recovery.
- Alternative: Include a safe, verified step, or make clear that no alternative is available yet.
- Next update: Say when and where the next update will be published, even if there is no estimated resolution time.
For example: “Some people can’t load their recent orders. We’re investigating the issue. You don’t need to resubmit orders that have already been confirmed. We’ll post another update at 4:00 p.m. on the status page.” Each statement should be verifiable. If you cannot confirm what is happening to existing orders, do not include that claim.
Communicate recovery and correct published information
When the service appears to be back, do not confuse deploying a change with confirming recovery. If checks are still underway, say that the team is verifying the result. Once recovery is confirmed, state which feature is available again and whether users need to take any outstanding action.
If an earlier message was incorrect, correct it clearly and directly. Explain which detail has changed and what information is now accurate. Do not silently edit an important claim if people may have acted on it. Avoid assigning blame before the investigation is complete, and keep any later explanation separate from the immediate guidance users need.
A closing update does not have to include a detailed root cause. It may be enough to confirm recovery, identify the affected period or feature if known, and share relevant next steps. If the cause is still being investigated, say so rather than presenting the incident as fully understood.
Checklist for preparing an incident communication protocol
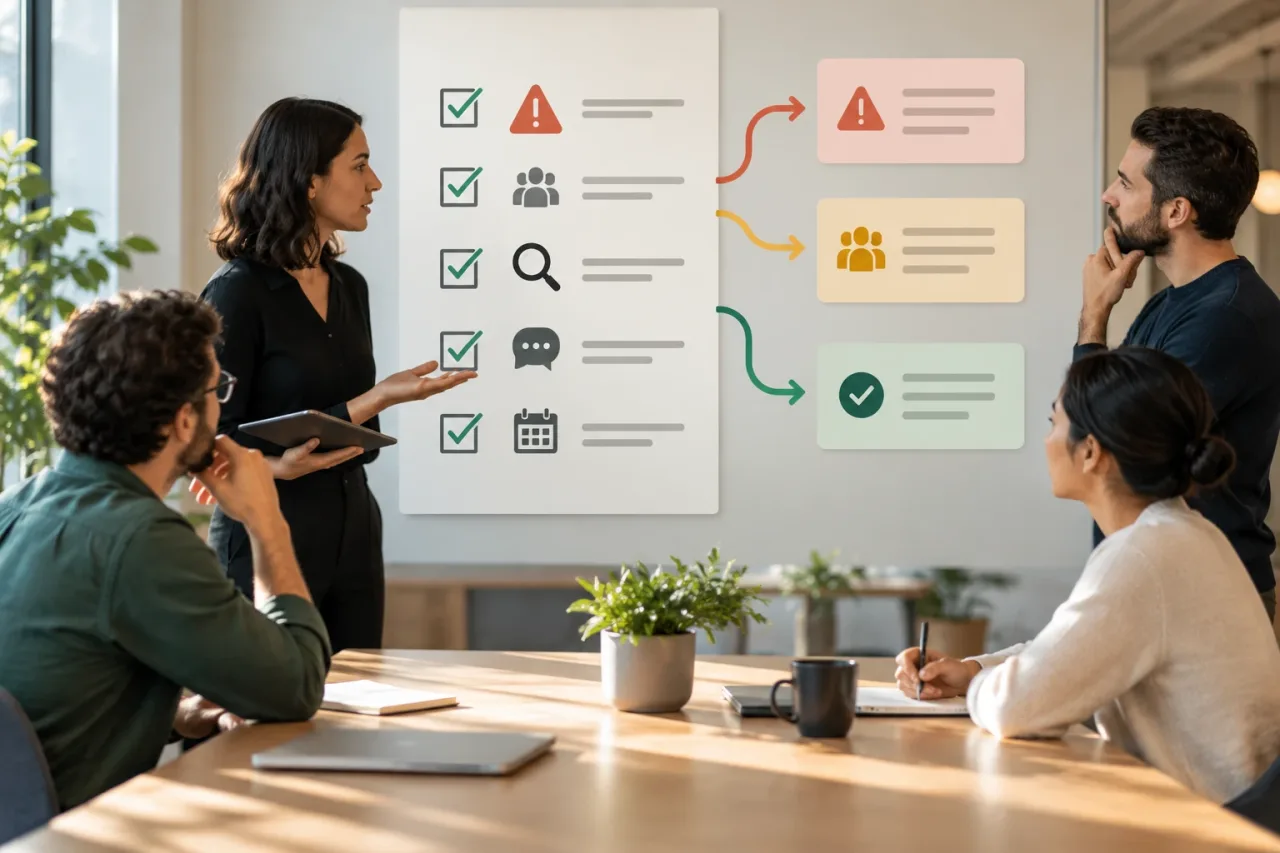
- Is the affected task or feature described in clear, understandable language?
- Is it clear what has been confirmed and what is still under investigation?
- Do the audience and channel match the known scope?
- Has any suggested alternative been verified and confirmed as safe?
- Is someone responsible for publishing, and is there a consistent source of status information?
- Has a time for the next update been set, even if there is no new information?
- Does the message avoid causes, timelines, or guarantees that cannot be supported?
- Is there a plan for confirming recovery and correcting earlier information?
A useful protocol does not require the same message for every incident. It provides criteria for making decisions quickly and consistently. When a team communicates the known impact, acknowledges the limits of its information, and provides updates at a predictable pace, it helps users take action without turning technical uncertainty into unnecessary uncertainty.