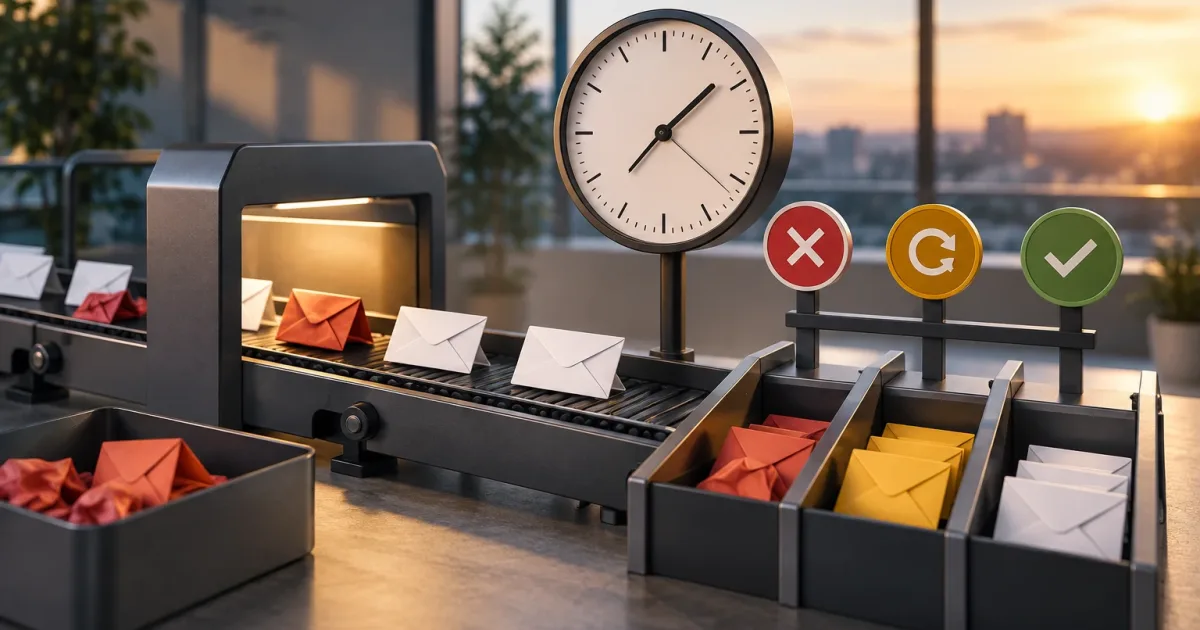
A failed message should not always be retried immediately or kept indefinitely. A pending payment notification, an inventory update, and an appointment reminder each have different levels of urgency and different value once they arrive late. That is why deciding how long to retry failed messages is a business and operational decision as well as a technical setting.
Your policy should answer three questions: which types of failure can be recovered from, how long it remains useful to execute the event, and what happens when that period ends. Agreeing on these answers reduces both silent failures and late executions that confuse customers or leave systems in inconsistent states.
Why a message that keeps retrying can become a problem
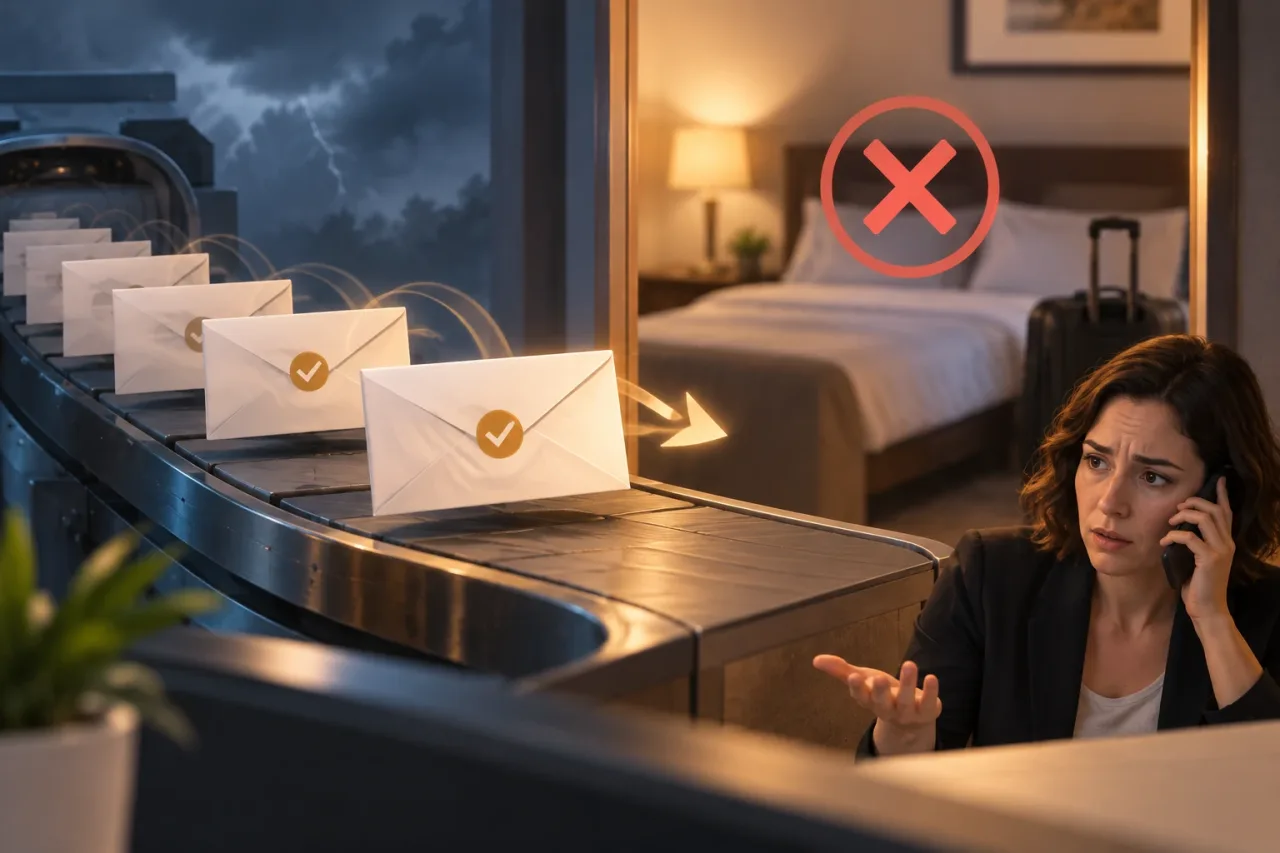
Retries can recover an operation after a brief interruption. But each new attempt also consumes resources and can produce unwanted effects if the action is performed after it has become obsolete. For example, sending a confirmation after a reservation has been canceled can lead to questions and support work, even if the message is eventually delivered.
The risk is not limited to delays. A queue of old events can make it harder to handle recent messages, and retrying a request with an uncertain outcome can duplicate an operation. The policy should therefore not maximize the number of attempts. It should maximize the chance of completing actions that still provide value while limiting the harm caused by late ones.
It helps to distinguish technical retention—how long the system keeps the event—from the validity window—the period during which it is permitted to execute. These periods may coincide, but they do not have to. An event could be retained after it expires so you can investigate what happened, without authorizing the system to process it automatically again.
Classify failures before setting the window
Error codes, integration responses, and process status can help determine whether a failure warrants another attempt. As an operational framework, divide cases into three groups and decide what action applies to each:
- Transient: Network interruptions, temporary service limits, or brief unavailability. These may justify another attempt, provided the action is still valid.
- Permanent: Invalid data, a nonexistent recipient, or a request rejected because of a condition that will not change in a few minutes. Repeating the request without correcting the cause rarely helps; it is usually better to stop and request a correction or intervention.
- Ambiguous: The connection was interrupted, and the system does not know whether the receiving service completed the operation. Before retrying, check the status when possible or apply safeguards against duplicate effects.
Not every service response has a universal interpretation. A temporary response may result from a persistent incident, while an apparently definitive error may be resolved by correcting data. Document the classification for each integration and review recurring cases. If you cannot reliably determine the cause, do not treat every failure as transient by default.
Set the period according to urgency, validity, and consequences
The retry window begins when the failure occurs and ends when the event should no longer execute automatically. To set it, agree on three criteria with business and operations teams:
- Urgency: How much delay can the process tolerate before it affects a decision, a commitment, or customer service?
- Validity: Until what point is the content or action still correct? Consider subsequent state changes, such as a cancellation, a resolved payment, or a past appointment.
- Consequence of lateness: What is the cost of executing after that point? It could be a confusing message, an incorrect update, or manual intervention. It might also be acceptable to complete an internal task with no visible impact.
Compare the window with the process's actual life cycle. A notice tied to an upcoming date may quickly lose its usefulness; a catalog synchronization may tolerate a longer delay. Do not adopt one period for every event simply because it makes configuration easier. Group events into service classes when their consequences are similar, and define exceptions only when there is a clear reason.
If validity depends on a changing state, counting hours from the first failure is not enough. Before a late execution, check whether the action is still permitted. When that check is unavailable, shorten the window or send the case for review rather than assuming the event remains valid.
Choose intervals and limits without creating retry storms
A constant, short interval can cause many events to be retried at once during an outage. Instead, consider increasing the time between attempts and setting a total duration or attempt limit. Gradually increasing the interval reduces pressure on the affected service and gives it time to recover. Adding random variation to intervals can prevent synchronized processes from calling again at the same time.
Parameters should reflect observed behavior, not an arbitrary number. Review how long typical interruptions last, how often retries recover, and how quickly an event loses its usefulness. Set limits that prevent endless retries, but make sure a brief failure has a reasonable chance to recover. If the service indicates that you should not retry yet, respect that signal when the integration allows it.
It is also worth separating the retry limit from concurrency. During a widespread failure, indiscriminately increasing attempts can make the incident worse. One warning sign is that pending events are getting older while the number of errors is rising. In that situation, check the service's health and limit the pressure instead of speeding up retries.
What to do when the window expires
Expiration should lead to an explicit outcome. Stopping retries without recording the result is equivalent to losing visibility. Define which of these options applies to each event type:
- Discard: For expired, low-impact events where execution is no longer valid. Keep enough information to explain the discard and identify patterns.
- Send for manual review: For cases with significant impact, an unresolved cause, or an ambiguous outcome. The review needs an owner, context, and an available action: correct the issue, retry in a controlled way, or close the case.
- Start a compensation: When the process needs to correct a partial effect or restore an agreed state. Compensation also needs conditions, an owner, and a record; it is not simply another retry.
Do not turn manual review into an ownerless queue. Establish who handles it, how they prioritize cases by age and impact, and what happens if no one acts within the agreed period. If operators cannot tell from the available data whether an event is recoverable or obsolete, the problem is the review design, not the team's speed.
Record what is needed to diagnose and act
For each event, keep an identifier that makes it traceable, its type, status, age, the number and time of attempts, the recorded cause, the next action, and the decision made at expiration. Include the destination system when there are multiple integrations. Avoid storing personal data or secrets that are not needed for diagnosis, and apply the relevant access and retention rules.
These signals help distinguish a window that is too short from an external incident: the proportion of messages that recover, time to recovery, the volume that expires, the most frequent causes, and the size and age of the pending review queue. Interpret metrics by event type. A high rate of successful retries does not justify extending the window if recovered cases arrive after they have lost value.
Checklist for agreeing on a policy
- What business effect does the event produce, and when does it become invalid?
- Which failures are transient, permanent, or ambiguous for each integration?
- What is the maximum window, and how do you check that the event is still valid?
- Which intervals and limits prevent excessive pressure and indefinite retries?
- On expiration, is the event discarded, reviewed, or compensated for? Who is responsible?
- Which data and metrics make it possible to explain the outcome and improve the policy?
Ultimately, how long to retry failed messages depends on how long it takes for the cause to disappear and how much value the action retains during that time. Set windows according to impact, limit attempts, treat permanent errors differently, and agree on an operational outcome. Then review the events that expire most often or require the most intervention: they usually point to the best opportunities to improve classification, the integration, or the process itself.