

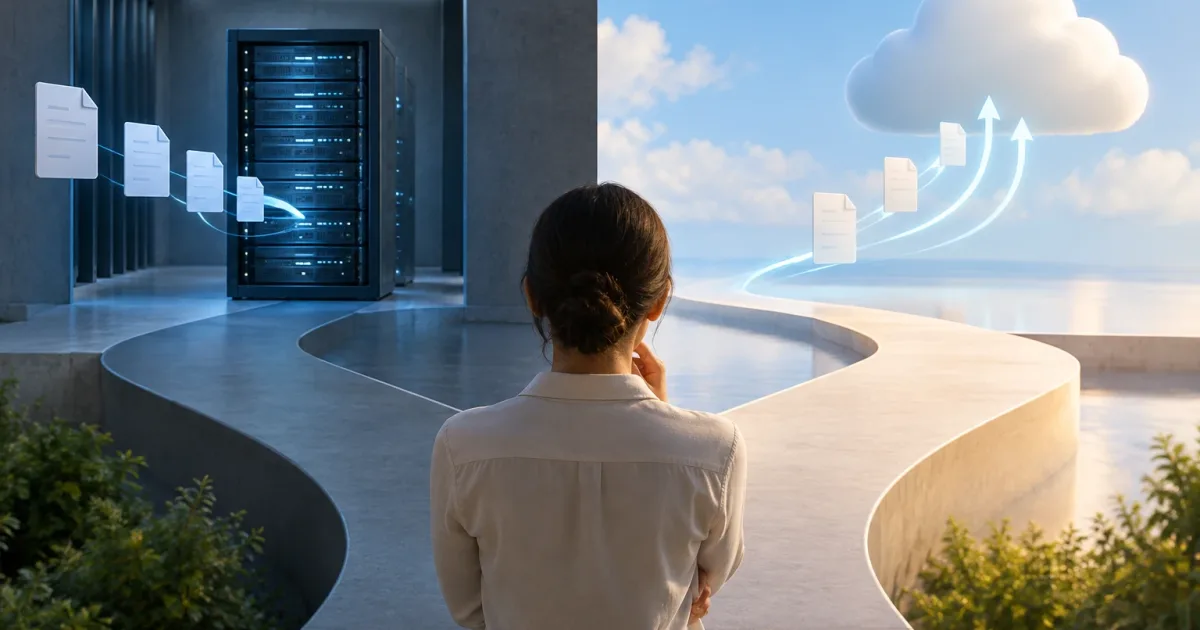
Adding file uploads can seem like a simple feature: a user selects a document and sends it. Yet that decision affects the user experience, security, operating costs, and the product’s ability to scale. An occasional image attached to a form does not create the same requirements as hundreds of large videos or documents that must be reviewed before they become available.
The key question is not which architecture is more modern, but which components should receive the data and what checks each file needs before it can be considered valid. In many products, the choice is between routing the file through the application server and allowing the browser to upload it directly to object storage, with authorization issued by the server.
Define the workflow before choosing an architecture
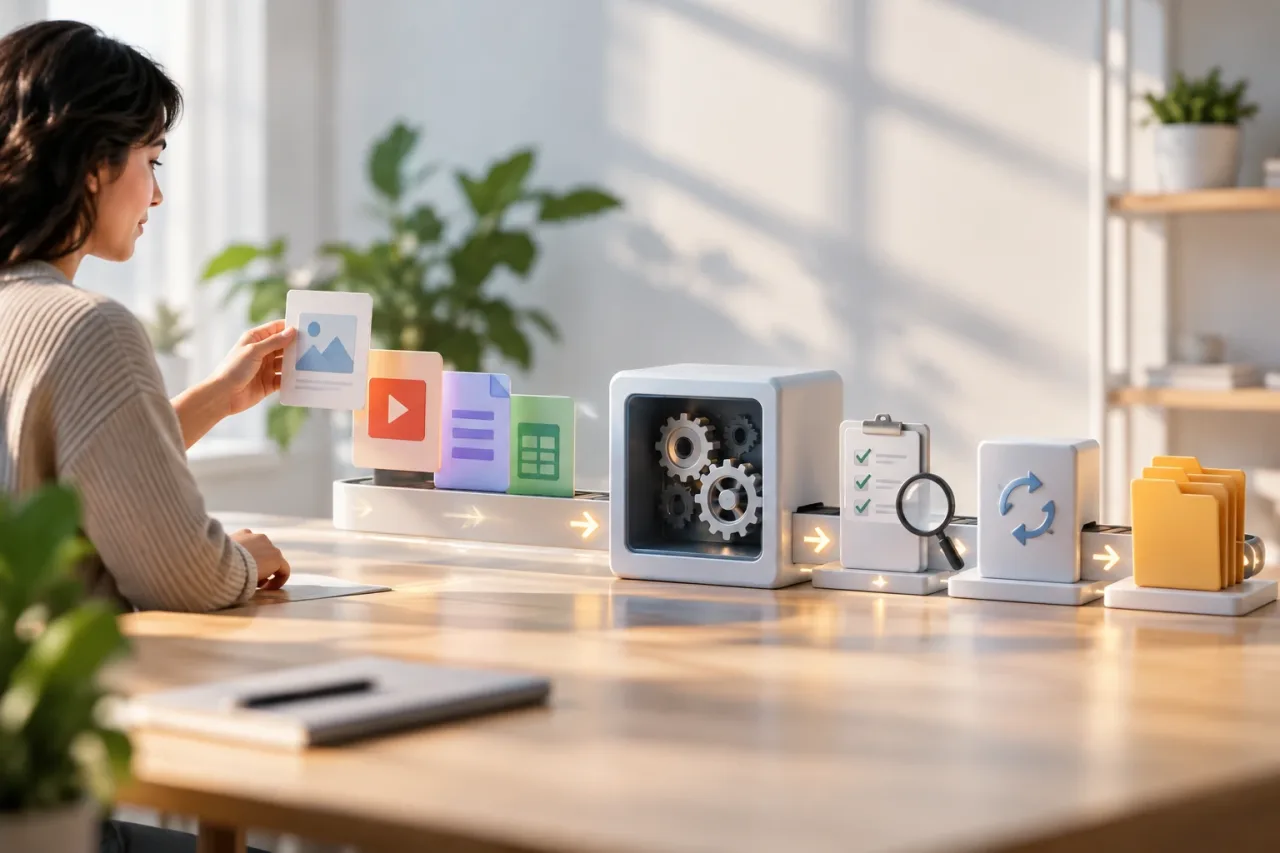
Start by describing what happens from the moment someone selects a file to the moment another part of the product can use it. Identify who uploads it, which formats are accepted, what the reasonable maximum size is, whether multiple uploads are allowed at once, and what happens after the files are received. Also clarify whether a file should be available immediately or wait for a review, conversion, or scan.
It is useful to distinguish three concepts that are often confused: receiving the file, storing it, and approving it for use. A completed transfer does not prove that the content is safe, belongs to the user, or complies with product rules. Designing the workflow with these stages kept separate makes it easier to change the architecture without changing the business rules.
- If the file is only attached to a small, straightforward operation, prioritize a route that is easy to build and operate.
- If file size, volume, or transfer duration matters, consider how to avoid sending all the traffic through the application.
- If a file requires review, processing, or approval, model that status explicitly instead of assuming it is ready as soon as the upload finishes.
Upload through the application server
In this model, the browser sends the file to an application endpoint. The server authenticates the request, applies checks, and then saves the content to the chosen storage. The logic can be easy to understand because uploads pass through the same point as the product’s other operations.
This is a suitable option when files are small or moderate in size, expected volume is limited, and each request needs to be validated as part of a specific business workflow. It can also be practical for an initial version: there are fewer visible components to coordinate, and the server can associate receipt with an account or record without exposing direct access to storage to the browser.
The limitation appears when the server becomes an intermediary for large amounts of data. The application has to maintain long-lived connections and transfer the content, even though storing it is not its main job. This can consume capacity, compete with normal requests, and make timeouts and dropped connections more consequential. Check size and duration limits across the entire route, including the browser, proxies, server, and final storage; changing just one limit does not resolve the others.
Upload directly to object storage
With a direct upload, the browser transfers the file to storage without routing its contents through the application server. The server is still necessary: it authenticates the user, decides whether they can upload, sets the conditions for the operation, and communicates how to complete the workflow. The application must not rely on browser-supplied data to decide by itself which user has permission or which location can be used.
This pattern can reduce the transfer load on application servers and is useful for large files, frequent uploads, or long-lived connections. In return, the product must coordinate several steps: reserving or identifying an upload, authorizing the transfer, receiving its result, and updating the file’s status. A completed transfer in storage and an updated record in the application can become out of sync if an intermediate step fails.
For that reason, define clear statuses such as pending, received, under review, and available, and establish how to reconcile them. Authorizations should have limited scope and duration. Do not expose permanent credentials or allow a temporary permission to enable more operations or locations than necessary. This approach adds integration and operational responsibilities; it is not automatically more secure or simpler.
Practical criteria for making a decision
Compare the options using product data and real constraints, not just optimistic forecasts. The architecture can evolve: it is reasonable to start with a simple route if the risk is controlled, provided its limits are understood and there is a clear signal for when to revisit the decision.
- Size and volume: The larger the files and the more simultaneous uploads there are, the more important it becomes to avoid having the application transport every byte. Use the product’s maximum limits, not the average file size, when designing for critical cases.
- Connectivity: Disconnections, slow networks, and accidentally closing the page have a greater impact on long transfers. Assess whether retrying from the beginning is enough or whether the product needs resumable transfers; do not promise resumption unless it is implemented end to end.
- Security and business rules: Determine whether authorization is needed by user, entity, or process stage, and whether the content must remain inaccessible until it has been validated.
- Post-upload processing: If information must be extracted, variants generated, or content reviewed, design processing as a separate stage and retain the ability to tell users its status.
- Operations: Compare the complexity the team can maintain, including permissions, alerts, cleanup of orphaned objects, and responses to partial failures.
File validation and protection
Validate before accepting an upload, then recheck what is necessary after it has been received. At the start, verify identity, permissions, allowed size, number of files, and their relationship to the requested operation. On the server or in a trusted process, check the received content: the name and type declared by the browser are not enough to confirm what a file contains.
Apply access controls so that a private file does not accidentally become public. Use internal references instead of turning a user-provided path or name into authorization. If the product allows files to be downloaded, decide who can do so and for how long; temporary links must not replace the permission checks in the workflow that issues them.
Untrusted files can also consume resources or contain unexpected content. Limit sizes and formats according to actual needs, avoid processing them with unnecessary privileges, and keep them isolated until the relevant checks are complete. If the use case involves special risks, consult the security guidance that applies to the file type and product context.
User experience and day-to-day operations
A progress bar is useful only if it reflects understandable information and does not conceal a stalled process. Show the status of each file, allow cancellation where possible, and provide a clear action when something fails. Define which errors can be retried and prevent a retry from creating duplicates or leaving several versions that appear valid. For long-running processes, tell users that the upload is complete but the file is still under review, rather than presenting both steps as one.
In production, monitor success and failure rates, upload duration, abandonment, and validation errors. Record operation IDs and statuses, but avoid putting sensitive content or unnecessary diagnostic data in logs. Set a policy for incomplete uploads and pending files that are no longer needed: without cleanup, they create clutter, costs, and uncertainty about which version is current.
Checklist before implementation
- Document expected sizes, formats, volume, and permissions, including maximums.
- Choose between routing uploads through the server and direct uploads based on transfer load and the team’s operational capacity.
- Define upload statuses and the conditions that allow a file to be used or downloaded.
- Test oversized files, disallowed formats, disconnections, repeated requests, and failures when updating the record.
- Verify that one user cannot read, replace, or associate another person’s files.
- Prepare metrics, alerts, and cleanup for incomplete transfers.
In short, the best architecture is the one that meets security and user-experience requirements without adding complexity the team cannot operate. For small uploads, routing them through the application may be sufficient. For large or frequent transfers, direct uploads can reduce the load on the application, provided authorization, statuses, and reconciliation are designed well. Revisit the decision when file sizes, volume, or the product’s use of those files changes.