

A digital pilot is not a reduced version of a full rollout, nor is it a demonstration intended to confirm a decision that has already been made. It is a controlled test designed to reduce a specific uncertainty: whether a solution can integrate into operations, deliver measurable value, and be sustained with reasonable effort.
Scope determines the quality of the learning. A pilot that is too small may work only because it avoids the difficult conditions of real operations. One that is too broad accumulates dependencies, edge cases, and coordination until it becomes a disguised implementation. The goal is to select a sample that represents the process and its relevant frictions without exposing the entire organization to a change that has not yet been validated.
For product, business, operations, and technology leaders, the key decision is not how many people to include. It is which hypothesis the pilot must resolve and what evidence will be sufficient to make the next decision.
Start with the decision the pilot must enable
Before selecting users or features, define the decision that will be unlocked when the test ends. Without a specific decision, the pilot will tend to collect general opinions, disconnected metrics, and additional scope requests.
Common decisions include expanding the solution to more teams, correcting a design before expanding, pausing until a dependency is resolved, or discarding the option being assessed. Each requires different evidence. For example, an automation pilot may show that it reduces handling time, but not necessarily that the input data is of sufficient quality to scale.
Turn the initiative into testable hypotheses
- Value: the new flow reduces time, errors, repeat contacts, or manual work in a defined case.
- Adoption: participants can complete the task without systematically relying on alternative channels.
- Technical feasibility: permissions, data, and integrations behave reliably under real conditions.
- Operability: support teams and owners can detect, address, and recover from incidents without improvising.
- Security and control: access and data handling comply with applicable rules before exposure is expanded.
Avoid objectives such as “validate the tool” or “test the experience.” They are too broad. A useful statement would be: verify whether the operations team can resolve standard requests through the new flow, with quality equal to or better than the current process and without increasing the support burden.
Define a representative test unit
Pilot scope can be limited by users, process, channel, region, case type, data source, or integration. Do not try to vary all these dimensions at once. Choose one primary unit and keep the others stable enough to interpret the results.
If adoption is the main risk, keep a familiar process and test different user profiles. If uncertainty is concentrated in an integration, limit participants and expose the solution to real data and events. If a new channel is being assessed, keep request types and the operating model tightly bounded.
Select participants for functional diversity, not availability
Highly motivated volunteers provide early signals, but they rarely represent day-to-day behavior. Include participants who reflect meaningful process variation: frequency of use, experience level, workload, approval needs, and reliance on other systems.
- Include regular users of the process to assess efficiency and quality under normal conditions.
- Include some less experienced profiles to identify comprehension, training, or design issues.
- Include operational owners who can assess exceptions, queue impact, and workload changes.
- Avoid concentrating the pilot in one team, shift, or manager if the future rollout will cover different conditions.
- Temporarily exclude groups for whom an incident would have disproportionate consequences until a recovery method has been validated.
Representativeness does not require reproducing the entire organization. It requires covering the differences that could change the decision. Document why those participants were chosen and which segments remain outside the scope, so a partial result is not presented as universal evidence.
Include the core flow and select exceptions deliberately
A common mistake is testing only the “happy path”: complete data, standard requests, trained users, and available systems. The pilot should include the flow that creates most of the value, as well as a limited set of situations that test its boundaries.
Classify cases into three groups. This distinction protects operations and prevents the exception list from turning the pilot into an endless project.
- Essential cases: frequent, high-volume situations or those critical to demonstrating the value proposition. They must be included from the start.
- Diagnostic cases: less common situations that could reveal a significant weakness, such as incomplete information, an additional approval, or a status change. Include them when there is a safe response.
- Deferred cases: rare, high-impact, regulated exceptions or cases dependent on systems that are not yet ready. Exclude them from the first phase, but record their volume, impact, and current treatment.
Excluding an exception does not mean ignoring it. There must be an exclusion criterion, an alternative route, and a date or condition for reviewing it. For example, if a request requires manual validation that the integration does not yet support, participants must know when to route it elsewhere and who takes ownership of the case.
Design operational limits before activating the test
Every pilot needs clear entry and exit rules. Define which transactions, users, or data can use the new solution; who can stop it; which signals trigger a rollback; and what the safe manual alternative is. The latter must not be an informal note: it must be tested, accessible, and assigned to an owner.
Set workload limits as well. If the system processes requests, establish an initial maximum volume and a way to monitor the queue. If it automates decisions, limit the decision type, amount, impact, or data set until consistent results are observed. An explicit limit is a learning tool, not a sign of low confidence.
Resolve the minimum dependencies needed to interpret the result
A failed pilot may reveal a poor solution, but it may also expose misconfigured permissions, incomplete data, an unstable integration, or insufficient operational support. It is not possible to remove every risk, but known blockers can be separated from the hypotheses under evaluation.
Prepare a brief readiness review with product, operations, and technology. At a minimum, it should cover:
- Data: source, expected quality, required fields, traceability, and handling of sensitive information.
- Access: authorized profiles, least-privilege principles, and participant onboarding and offboarding.
- Integrations: involved systems, behavior on failure, retries, duplicates, and the owner of each interface.
- Support: help channel, hours, priority levels, response times, and escalation path.
- Observability: events, errors, status changes, and metrics needed to investigate an incident.
- Ownership: one person accountable for the business decision and another for technical and operational continuity.
When a dependency is not ready, three options are valid: delay the start, reduce scope to avoid it, or introduce a controlled manual intervention. The poor option is to hide it and later attribute its effects to user experience or solution performance.
Measure learning, not only use or satisfaction
Activity alone does not confirm value. A pilot may have many logins and still shift work to another team, create rework, or function only because it receives exceptional attention. Combine quantitative metrics with qualitative case reviews.
- Adoption: the proportion of participants completing the flow and frequency of use compared with the previous process.
- Quality: errors, corrections, duplicates, abandonment, and compliance with process rules.
- Time: task duration, waiting time between steps, and total time to resolution.
- Operational effort: manual interventions, support contacts, follow-up hours, and transferred workload.
- Reliability: integration failures, perceived availability, recoveries, and recurring incidents.
Establish a baseline before starting. If reliable historical data is unavailable, measure a sample of the current process over a limited period. Then define a review cadence: frequent monitoring for incidents and a decision review at the end of the period or once a sufficient case volume has been reached.
Set exit criteria and approve scope before launch
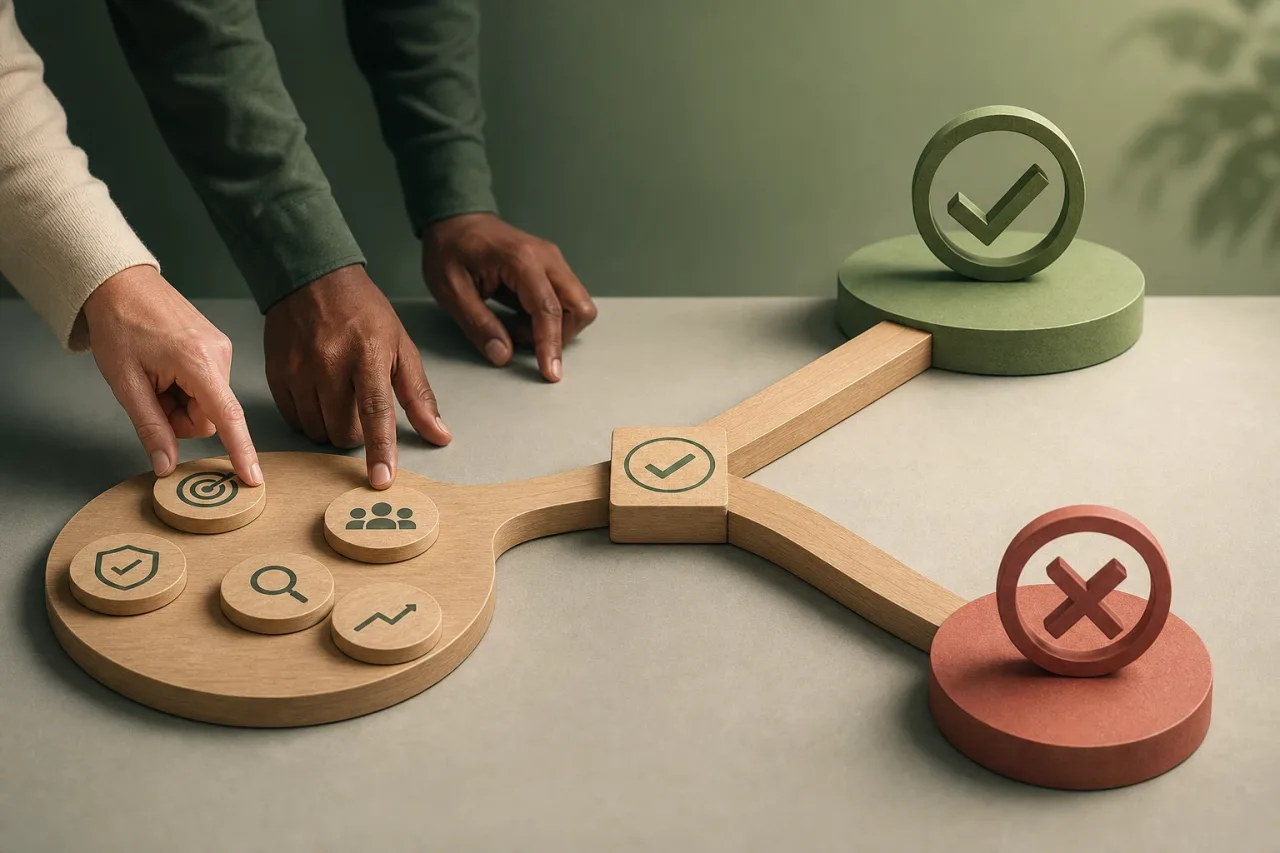
Exit criteria should be agreed before the result is known. There is no need to set an artificial number for every metric, but it is important to define which combination of signals would justify each path.
- Expand: the core flow delivers value, participants use it consistently, errors are manageable, and operations can support the increase.
- Redesign: there is interest or potential value, but recurring experience, data, training, or integration frictions prevent a safe expansion.
- Pause: a critical dependency, security risk, or unexpected operational burden prevents valid evidence from being obtained.
- Discard: even under controlled conditions, the solution does not improve the process or requires more effort than the expected benefit warrants.
Before activating the pilot, confirm that there is a priority hypothesis, a representative group, defined essential and diagnostic cases, documented exclusions, named owners, active support, a tested manual alternative, metrics with a baseline, and a scheduled decision meeting. If any of these elements is missing, the scope is not ready.
A good pilot does not try to prove that everything will work. It seeks to reveal early, with bounded risk, what must be retained, corrected, or discarded before scaling.