

A test can show more conversions while also increasing errors, support requests, or the time it takes to complete a task. The headline figure looks favorable, but the cost to users or operations raises a legitimate question: should you launch, revise, or stop?
The decision is not about choosing the metric that best supports a preference you already have. It is about comparing the result with a hypothesis, assessing the quality of the evidence, and deciding which risks are acceptable. This framework helps you decide the outcome of a product experiment without reducing it to a single number or treating every discrepancy as a reason to extend a test indefinitely.
Why a favorable primary metric is not enough
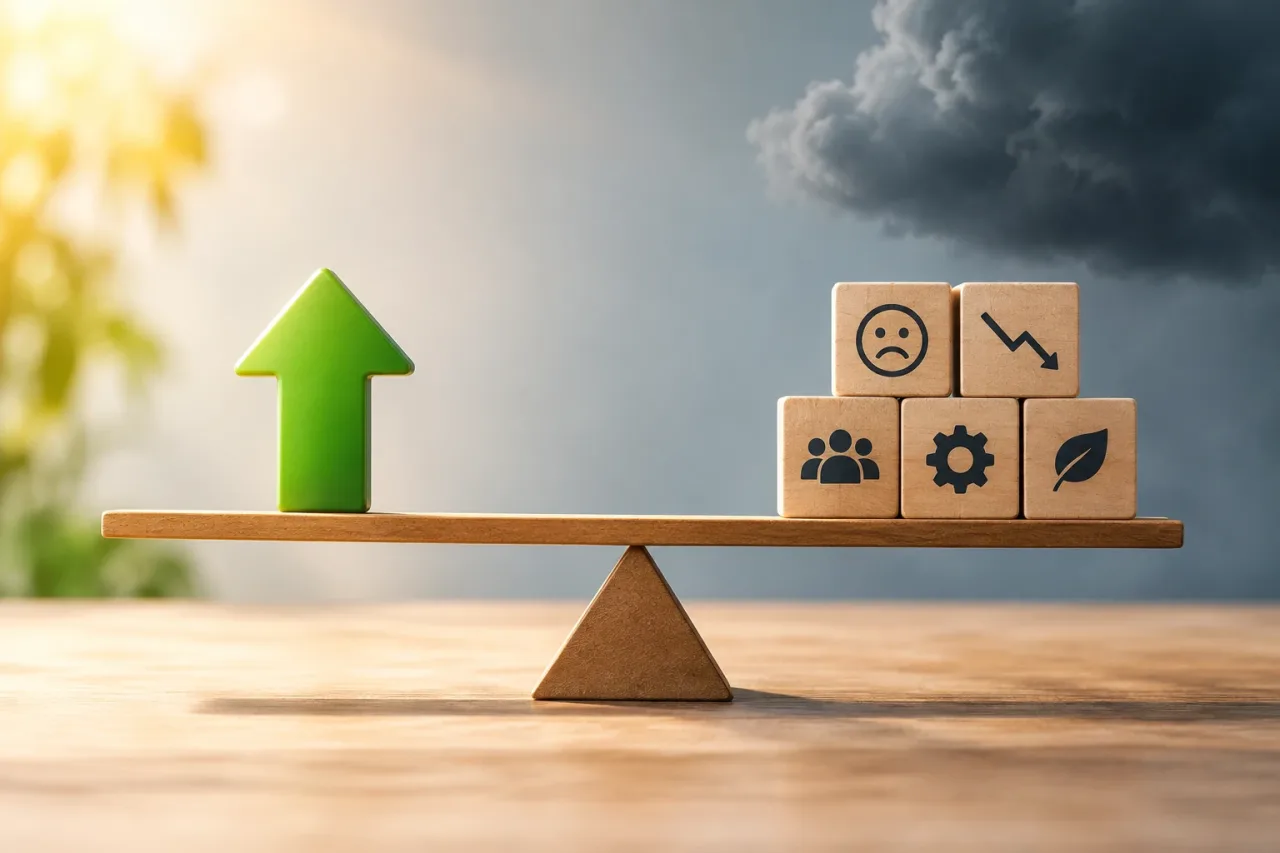
The primary metric represents the outcome the intervention is intended to change: for example, completing a purchase, activating an account, or booking an appointment. It matters because it makes the objective explicit. But an increase in that outcome does not, by itself, prove that the change is worthwhile overall.
An apparent improvement could come with more cancellations, payment errors, customer service contacts, or abandonment of a later task. It could also shift activity between steps without improving the final outcome. A new screen, for example, might increase clicks on “continue” without increasing completed purchases.
It helps to separate three questions:
- Did the intended outcome move? The primary metric addresses the immediate hypothesis.
- Did the change cause meaningful harm? Guardrail metrics reveal important costs or deterioration.
- Does the evidence let us attribute the movement to the change? Instrumentation quality, assignment, and the observation period all shape the interpretation.
A favorable answer to the first question does not automatically resolve the other two. A change should move forward only if its benefit is credible enough and its costs remain within acceptable limits.
Before testing: define the hypothesis and decision criteria
Before starting the test, write down what is changing, for whom, and why you expect it to produce an outcome. The hypothesis should describe a testable relationship, not a solution that is already assumed to be correct. For example: “Simplifying this step will reduce drop-off among new users because it removes a request for information they do not need at that point.”
Also define the eligible population, the primary outcome, and the period or volume needed to evaluate the test. Do not choose the duration solely because striking numbers appeared in the first few days. Consider relevant usage cycles, known seasonality, and the time needed for downstream effects, such as returns or support requests, to emerge.
Agree on the possible decisions and the signals that would trigger them before looking at the results. There is no need to pretend that everything can be reduced to one statistical threshold. But you should distinguish between:
- Conditions for moving forward: a sufficiently convincing benefit, with no unacceptable deterioration in guardrail metrics.
- Conditions for stopping: clear harm, operational failure, or a risk that the improvement does not justify.
- Conditions for investigating or iterating: an uncertain result, a fixable problem, or data that does not support a reliable conclusion.
Set limits according to context. A small decline in a secondary metric may be tolerable if the impact is reversible and the benefit matters; an increase in errors that prevents completion of a critical task may require a stop, even if conversion rises. Limits should reflect consequences for users and the business, not just statistical convenience.
Which guardrail metrics to monitor and how to set alerts
Guardrail metrics monitor effects that the intervention must not materially worsen. Which ones you choose depends on the change. A registration adjustment may call for monitoring errors, later activation, and support contacts. A change to the checkout process may require reviewing failed payments, cancellations, returns, and support handling times.
Choose a small number of metrics that represent specific risks and can be measured reliably. Adding dozens of indicators makes it harder to distinguish an important signal from random fluctuation. For each metric, document:
- the harm or cost it is intended to detect and the population it applies to;
- its usual level and how it is calculated, including the denominator and time window;
- what degree of deterioration would be concerning and what action it would trigger;
- whether the data arrives late or could be affected by instrumentation failures.
An alert threshold is not necessarily a definitive statistical test. It can be an operational rule for pausing and reviewing, especially when potential harm is serious. If an alert is triggered, first check that the measurement is working and the comparison is valid; do not ignore the risk while waiting for a perfect conclusion.
Interpreting conflicting signals without picking the convenient number
When metrics disagree, do not average them or choose after the fact whichever one favors your preferred option. Examine the expected causal chain: did the change affect the intended step? Does the effect carry through to the downstream outcome? Is the secondary metric a direct cost, a temporary consequence, or an indicator that does not reflect actual harm?
Also review data quality. Verify that assignment to each variant worked, events were recorded consistently, and the populations are comparable. Check whether simultaneous changes, interruptions, or campaigns affected behavior. If measurement is broken, the result is neither “positive” nor “negative”: it is inconclusive until the limitation is resolved.
Distinguish magnitude from certainty. A small but consistent change may be valuable if it affects many interactions; a large change based on little data may be fragile. Do not confuse an absence of evidence of harm with evidence that no harm exists, especially for delayed or rare consequences.
When the primary effect improves and a guardrail metric worsens, ask whether the deterioration exceeds the agreed limit, whether it materially affects the people concerned, and whether there is a testable explanation. If the cost is acceptable and within the limit, moving forward with monitoring may make sense. If it crosses an important limit, the primary improvement does not automatically offset it.
Launch, iterate, extend, or stop
Launch when the evidence supports the objective, there are no signs of harm beyond the agreed limits, and operations can sustain the change. The rollout can be gradual, with monitoring and the ability to reverse it; it does not have to reach the entire population at once.
Iterate when the hypothesis remains plausible but the results point to a specific, fixable problem. For example, the simplified flow may work, while an ambiguous instruction generates support requests. Form a revised hypothesis and, whenever possible, test the new change separately so you can tell what produced the result.
Extend the test only if relevant information is missing and can be collected through a valid test. First specify what uncertainty the extension will resolve, what additional data would change the decision, and when you will review the results again. If nothing you observe would alter the choice, extending the test only adds cost and opportunities for biased selection.
Stop if harm exceeds the limit, the change fails at an essential task, or the hypothesis is weakened and there is no reasonable path to correction. Stopping a variant does not invalidate what you learned: it may reveal a design constraint or operational need that is better addressed another way.
Different segments and reversible decisions
An average result can hide differences between groups. However, do not turn every observed difference into a segmented policy: the more groups you review, the more likely you are to find random variation. Give greater weight to segments defined before the test, with a clear rationale and enough information to interpret them.
Check whether a difference is consistent, relevant, and explainable before acting on it. If new users appear to benefit while returning users do worse, one option may be to design a different experience for each context—but only if it can be implemented, measured, and maintained without creating confusion or disproportionate costs. When the evidence is weak, record the signal as a hypothesis for a future test, not as a conclusion.
Finally, document the decision: the hypothesis, population, period, metrics, alerts, result, uncertainties, and person responsible for follow-up. Specify what new signal would justify revisiting the decision and how the change could be reversed. A documented, reversible decision does not eliminate risk, but it makes it possible to act thoughtfully, learn from real-world effects, and correct course without mistaking a favorable metric for automatic approval.