

A rate limit protects an API from traffic spikes, integration errors, and usage that could degrade the service. It also affects the experience of those who depend on it: a policy that is too strict can interrupt legitimate processes, while one that is too permissive leaves little room to respond to overload.
The decision is not about choosing a universal number of requests per minute. It is about identifying which resource needs protection, understanding normal usage patterns, and making the limit clear and predictable. This guide offers criteria for setting quotas, responding when they are exceeded, and reviewing the policy based on evidence.
What rate limits solve—and what they do not replace
Rate limits control how much a client or process can consume over an interval, or how many operations it can keep running at the same time. They help distribute capacity, contain bursts, and reduce the impact of errors such as a loop that repeatedly makes calls without pausing. They can also support a commercial offering with defined usage tiers.
However, a quota does not replace capacity planning, protection against attacks, or efficient API design. A limit can ease pressure, but it does not fix an expensive query, a slow dependency, or a flawed retry strategy. Nor does it guarantee by itself that every consumer will receive a fair share of resources.
Before setting a limit, clarify its purpose: is it intended to protect an expensive operation, reserve capacity for different clients, or establish a service condition? If there are several objectives, separate them. Technical protection policies and commercial rules may overlap, but they should not be confused: they have different criteria for change and different communication needs.
Identify consumers and operations before setting numbers
A quota is useful only if the system can attribute requests to a stable identity. Determine whether the consumer is an account, a registered application, a credential, an internal team, or an end user. An IP address can provide an additional signal, but it does not always identify a client: several people may share one, and a single client may change addresses.
Next, classify operations. Reading a cached resource usually does not cost the same as generating a report, starting an export, or running a broad search. Applying one limit to every endpoint is simpler to explain, but it can treat calls with very different costs unequally.
Review actual traffic and expected scenarios before setting values. Look for patterns by consumer, endpoint, time of day, request duration, concurrency, and errors. Also check which integrations process batches or perform periodic synchronization. A legitimate integration may concentrate calls in a short window without behaving like sustained traffic.
- By account or application: makes it easier to set a stable client policy, provided the identity is properly linked.
- By operation: helps protect functions with different costs or capacity requirements.
- By shared resource: helps contain pressure on a database, provider, or shared process.
The chosen scope should match the resource being protected. If a credential-based limit can be bypassed by creating new credentials, the account may be the right unit. If an operation shares a resource with other endpoints, an individual quota may not be enough to protect it.
Quotas, concurrency, and bursts: choose the right control
A quota limits the volume of requests within a period. It is useful for expressing a usage budget and is easy to communicate, but the interval and what counts as a request must be clearly defined. A fixed window can allow traffic to cluster around the moment the period changes; a sliding window or token-based system can smooth that effect, but is more complex to implement and explain.
A concurrency limit restricts how many operations can be active at once. It is useful when requests take a long time or consume resources while running. It does not necessarily limit total volume: a client could complete many small operations, one after another. For that reason, it can be combined with a quota when both risks matter.
Burst control allows a brief spike without accepting a high rate indefinitely. It can suit synchronization or process startup, provided the service can handle the spike. Do not allow bursts simply because average traffic seems low: available capacity during the spike matters too.
To choose a control, ask what is likely to degrade first: the accumulated work budget, the number of simultaneous operations, or immediate capacity. Use the simplest control that protects against the observed risk. Combining mechanisms without a clear reason can make limits difficult to troubleshoot and produce conflicting messages.
Respond to excess usage predictably
When a consumer exceeds a temporary limit, a rejection response should be distinguishable from an unexpected service failure. In many cases, HTTP status code 429 indicates that too many requests have been received within a period. If the system can estimate when it will accept another request, it can communicate that using the Retry-After header. The response should also explain which limit was reached and where to find the applicable policy.
Do not promise a recovery time the system cannot guarantee. If it is not possible to say when capacity will become available, avoid suggesting immediate retries. Clients should use exponential backoff, limit their attempts, and, where appropriate, add random jitter to the waiting time so they do not all retry at once.
If a request starts an expensive or non-idempotent operation, specify how a rejection should be handled and whether it is safe to submit the request again. A client should not interpret every error as permission to repeat an operation without limit. Also document the differences between an exhausted quota, an invalid credential, and temporary unavailability.
Design transparent, reviewable exceptions
There may be legitimate reasons to adjust a quota: a migration, an agreed synchronization, or a demonstrated change in usage patterns. Define who can request an exception, what information is required, who approves it, and when it will be reviewed. Record its scope, duration, and owner so it does not become a permanent rule by default.
Avoid informal exceptions tied to a particular person or to agreements the operations team does not know about. If a change responds to a commercial condition, coordinate communication between product, business, and technology teams. If it addresses a temporary technical need, make the criteria for removing it clear.
Quotas can change, but the process should not surprise active integrations. Give advance notice of significant changes, state who is affected, and provide a migration path where possible. Publish current limits and explain whether they are guaranteed values or thresholds subject to review. Transparency about change is part of the policy, not an administrative detail.
Review metrics without rewarding abusive retries
Monitor both accepted usage and rejected requests. Break the data down by consumer and operation, and relate it to latency, errors, concurrency, and pressure on dependencies. An increase in 429 responses may indicate abuse, but it can also point to a poorly calibrated quota, a product change, or an integration that was not given adequate notice.
Interpret signals together. If a client occasionally reaches the limit during a planned task and capacity remains available, the burst policy or interval may not fit its usage pattern. If several consumers simultaneously increase latency and saturate a dependency, raising their quotas could make the problem worse.
Count and analyze retries: many rejected attempts can inflate traffic and obscure actual demand for work. Look for repeated sequences without pauses, clusters just after a window resets, and failed calls repeated without changes. Share these findings with the consumer where possible, and measure the effect of each adjustment before extending it to everyone.
Checklist for publishing a policy
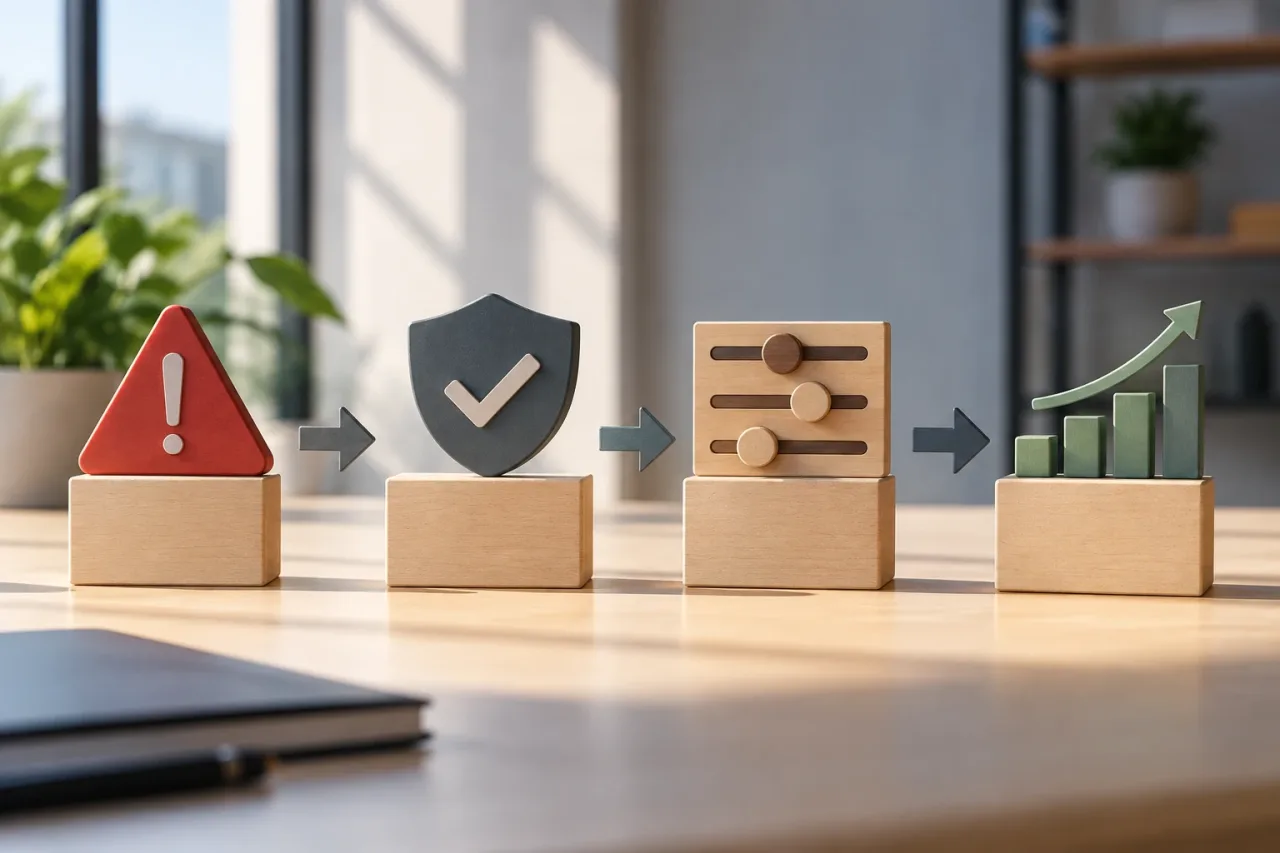
- Define the resource or risk each limit protects.
- Identify the consumer with a stable key and explain how its credentials are grouped.
- Separate operations when their costs or usage patterns differ.
- Specify the unit, period, scope, concurrency, and burst behavior.
- Document the response to excess usage and retry instructions.
- Establish an auditable process for exceptions and changes.
- Monitor rejections, retries, latency, and pressure on resources.
- Review the policy using data and communicate changes before applying them where feasible.
The best policy is not the one that allows the largest number of calls, but the one that protects the service without making usage unpredictable for clients and internal teams. Start with the specific risk, apply understandable limits, and adjust them only when metrics and integration patterns support the decision.